


We went looking for the published success rates in this industry. Counting only web unblocker products, so like-for-like, the numbers on the public record in 2026 run from 40% to a flat 100%, and most of them are defensible on their own terms.
Very little of that gap is about lying. Most of it comes down to definitions: whether a CAPTCHA page counts as a success, whether retries are included, which sites got tested, how many requests were sent, and over what duration.
Change any one of those and the same service reports a wildly different figure.
So this guide skips the part where we tell you our number is bigger. Instead, it covers:
- The five things that move a success rate by tens of points with no change to the underlying service.
- The four metrics that actually carry information, and how to define them so they do.
- A test protocol you can run against your own targets in two weeks, plus the questions that make a vendor’s answer checkable.
You won’t find a headline success rate anywhere in here, including ours. A single number describing web scraping reliability isn’t a property of a provider. It describes a traffic mix, a retry budget, a measurement window, and a definition of success, and once you strip those away, there’s very little left to compare.
1. Why web scraping reliability numbers cannot be compared
Everyone in this category advertises reliability, but hardly anyone defines it.
Spend an afternoon reading the marketing pages, docs, and third-party benchmarks for one unblocking product, and you’ll collect figures that cannot all be describing the same thing.
Vendor documentation quoting one number while the same vendor’s marketing site quotes a higher one. A “typically 100%” on a partner listing. Two benchmarks from the same publisher, in the same year, more than 25 points apart because they used different target sites and concurrency levels. A third-party speed test republished next to a vendor average that contradicts it.
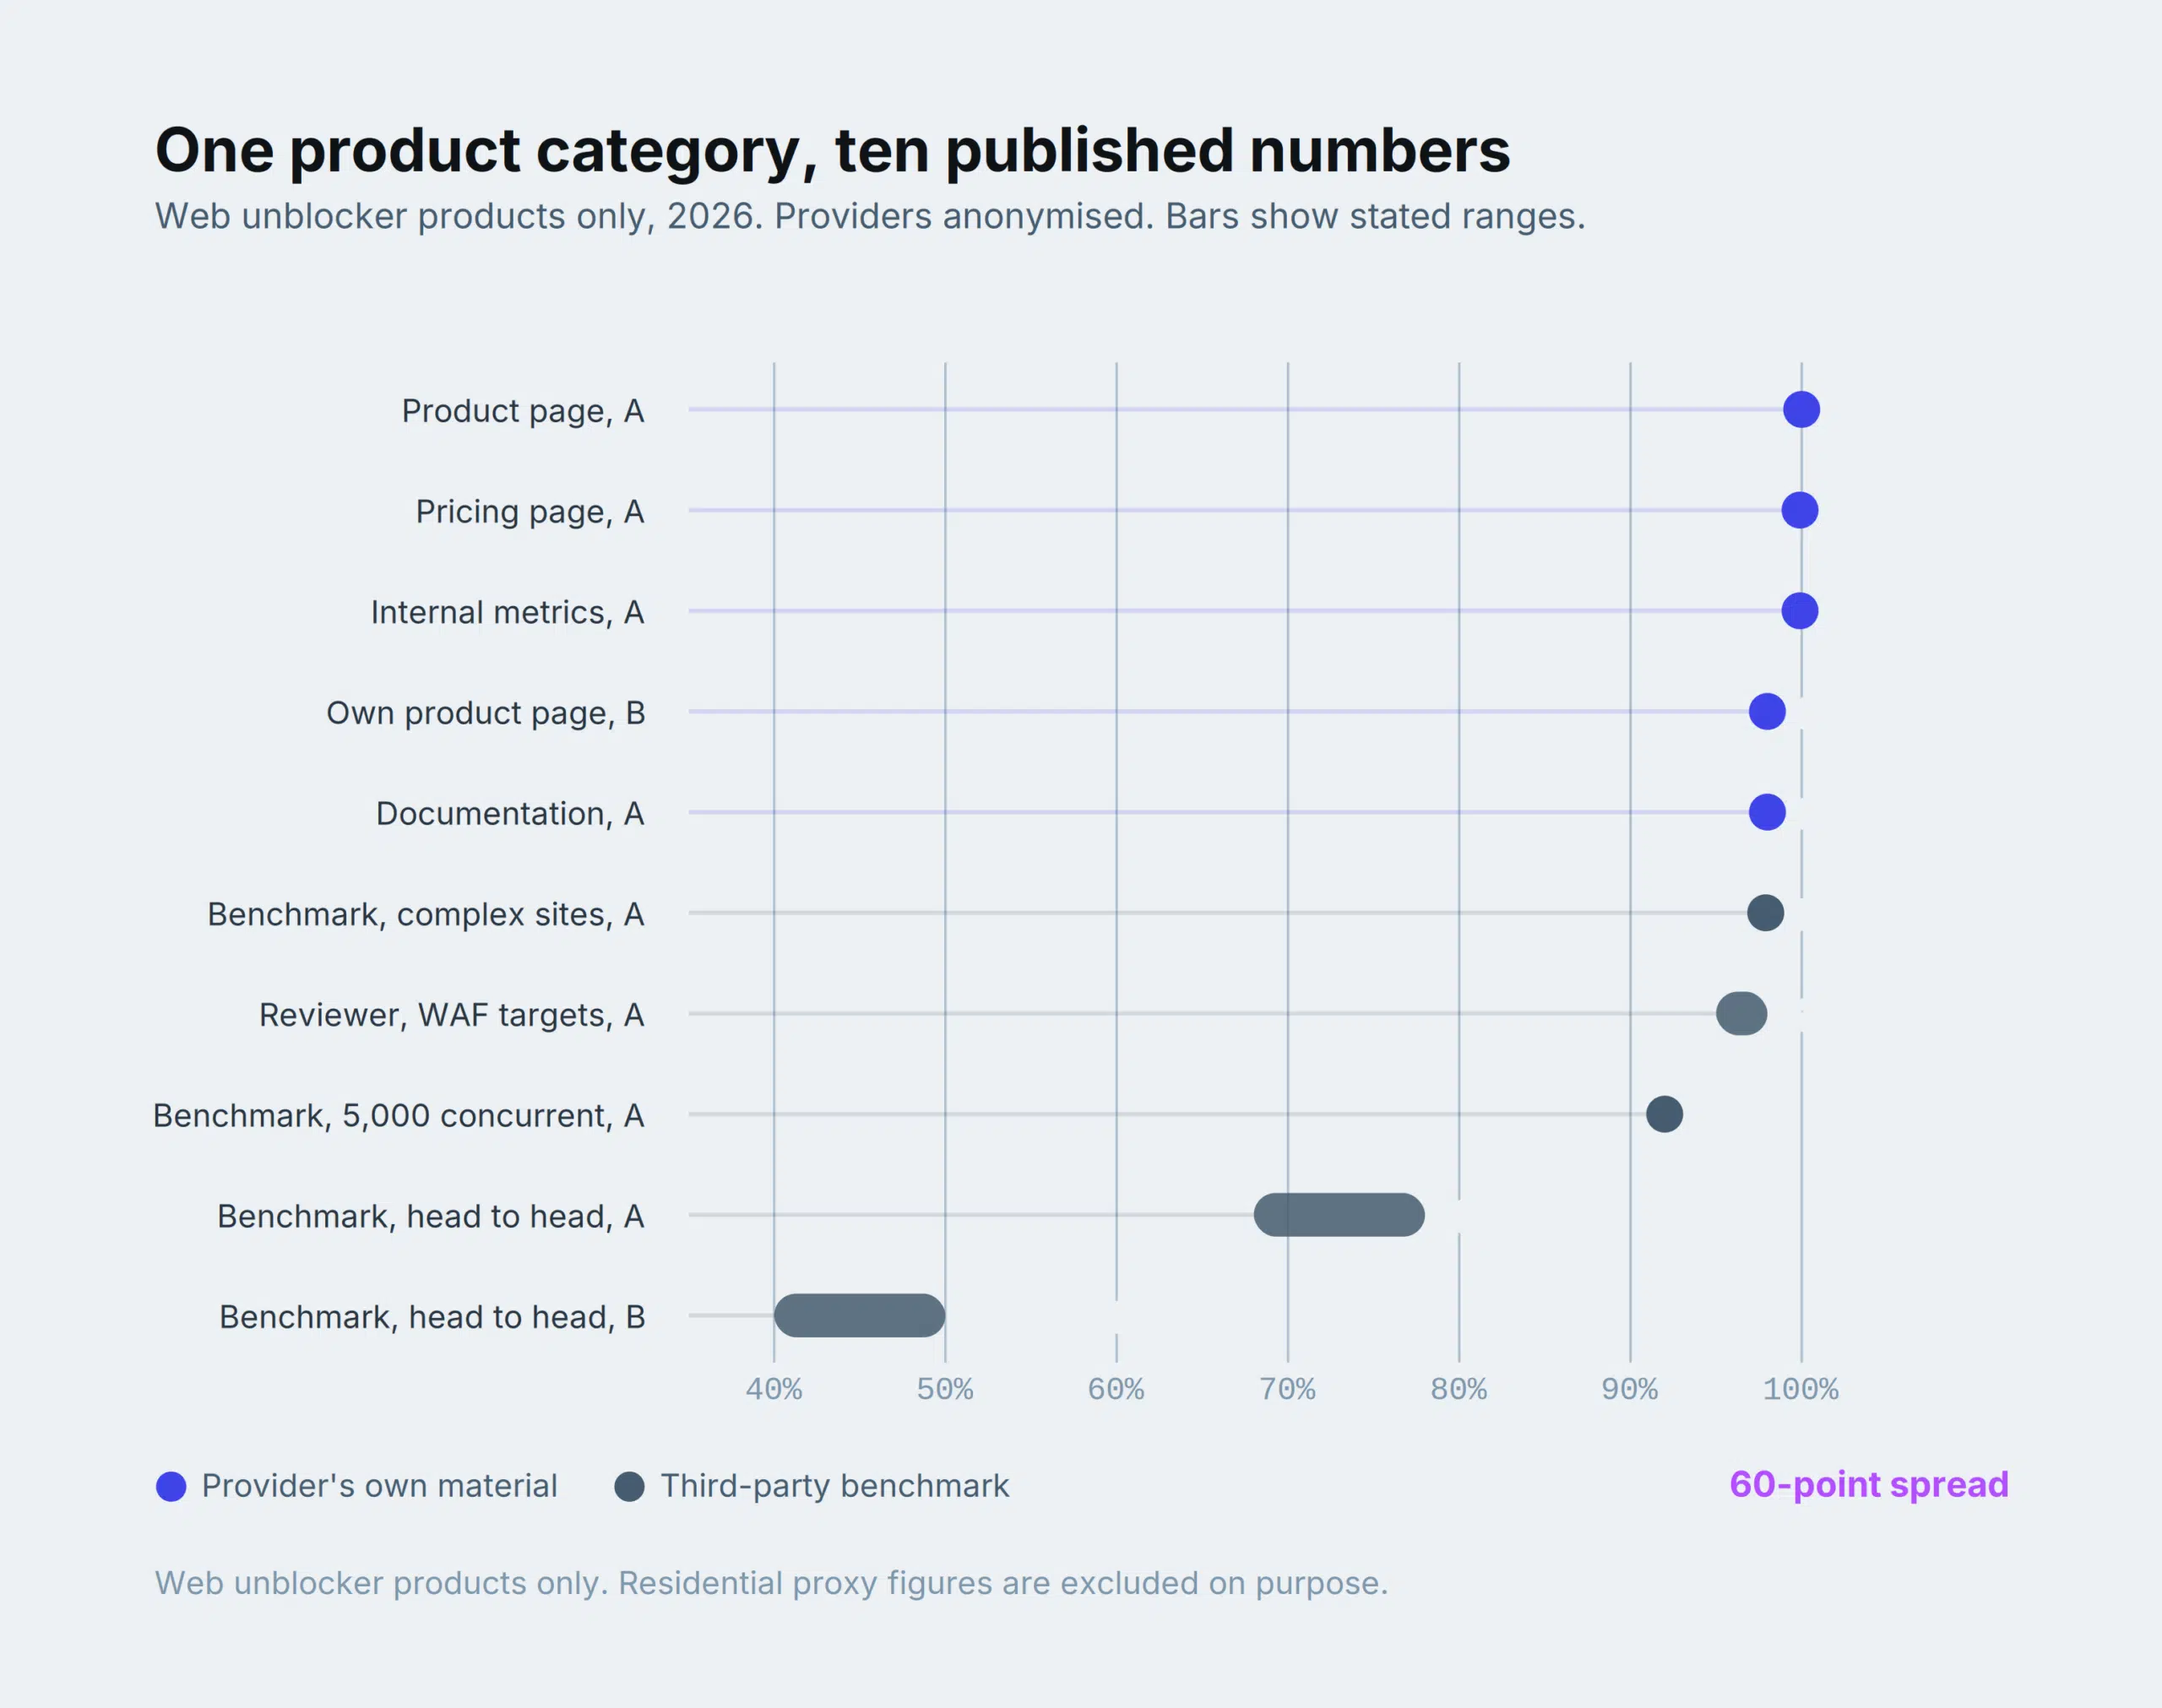
Figure 1. Every figure here is real, publicly stated, and about an unblocking product. Providers are anonymised because the point isn’t who said what.
Buyers do the sensible thing with this and stop believing all of it. Which is bad for buyers, who then have nothing to compare, and bad for the providers who genuinely are reliable, since credibility has stopped being purchasable with numbers.
What would help is not a better number but a habit of saying what the number means. We think that’s a standard the whole category would benefit from, so the rest of this document is our attempt at writing one, along with what it forces us to change about our own claims.
If you want to see how vendors currently position against each other, our comparison hub is a fair sample of the genre, including our own pages.
2. What providers actually publish about success rates
Here is the 2026 picture, source type by source type, for two providers in the same product category:
| Where it appears | What it says it measures | Figure |
|---|---|---|
| Provider A, product page | Success rate, “typically” | 100% |
| Provider A, pricing page | Retry and CAPTCHA logic gets “near” | 100% |
| Provider A, internal metrics, via a review | Unblocker average | 99.9% |
| Provider B, own product page | Unblocker success after switching, customer quote | above 98% |
| Provider A, product documentation | Unblocking product success rate | 98% |
| Independent benchmark, complex sites | Unblocker across Amazon, Google and similar | 97.9% |
| Independent reviewer, WAF targets | Unblocker against DataDome and Cloudflare | 95% to 98% |
| Independent benchmark, by concurrency | Unblocker at 5,000 concurrent requests | 92% |
| Independent benchmark, head-to-head | Provider A unblocker | 68% to 78% |
| Independent benchmark, head-to-head | Provider B unblocker | 40% to 50% |
Every row is an unblocking product. We left the residential-proxy figures for the same two vendors out, even though they show the same pattern, because putting them in the same table would be the exact mistake this guide is describing.
Two details in that table are more useful than the rest. The first is a gap that shows up at category level.
One benchmarking publisher reported that connection success against a small, non-blocking test page ran at 95% or better for most leading providers, while average success against popular real targets for those same providers sat around 80%. Same infrastructure, roughly 15 to 19 points of difference, and the only thing that changed was whether the target was a 6KB CDN page or Amazon.
The second is that the benchmarks disagree with each other, not only with the vendors. One publisher fires a few million connection requests over about three weeks at a small CDN endpoint. Another runs roughly 86,400 requests a month against real commercial sites. A third tests scraping APIs twice a month across a rotating target list, and changed that list from 11 sites to 12 between two consecutive 2026 reports. Across that third publisher’s mid-2026 runs, overall success rates for the eight APIs tested ranged from about 62% to about 97%.
A provider can therefore look excellent in one independent test and mediocre in another, in the same quarter, with nobody having done anything wrong.
3. Why do web scraping providers publish different success rates?
None of these is about engineering quality. All of them are decisions the publisher makes, and almost none get disclosed.
3.1 What counts as a successful scraping request?
The weakest definition available is “the server returned 200”.
An HTTP 200 will happily carry a bot-detection interstitial, a CAPTCHA challenge, an empty shell waiting for JavaScript that never ran, a geo-block notice, or a soft 404 that looks like a product page and contains no product.
Every one of those breaks a pipeline. Every one of them counts as a success if you’re tallying status codes.
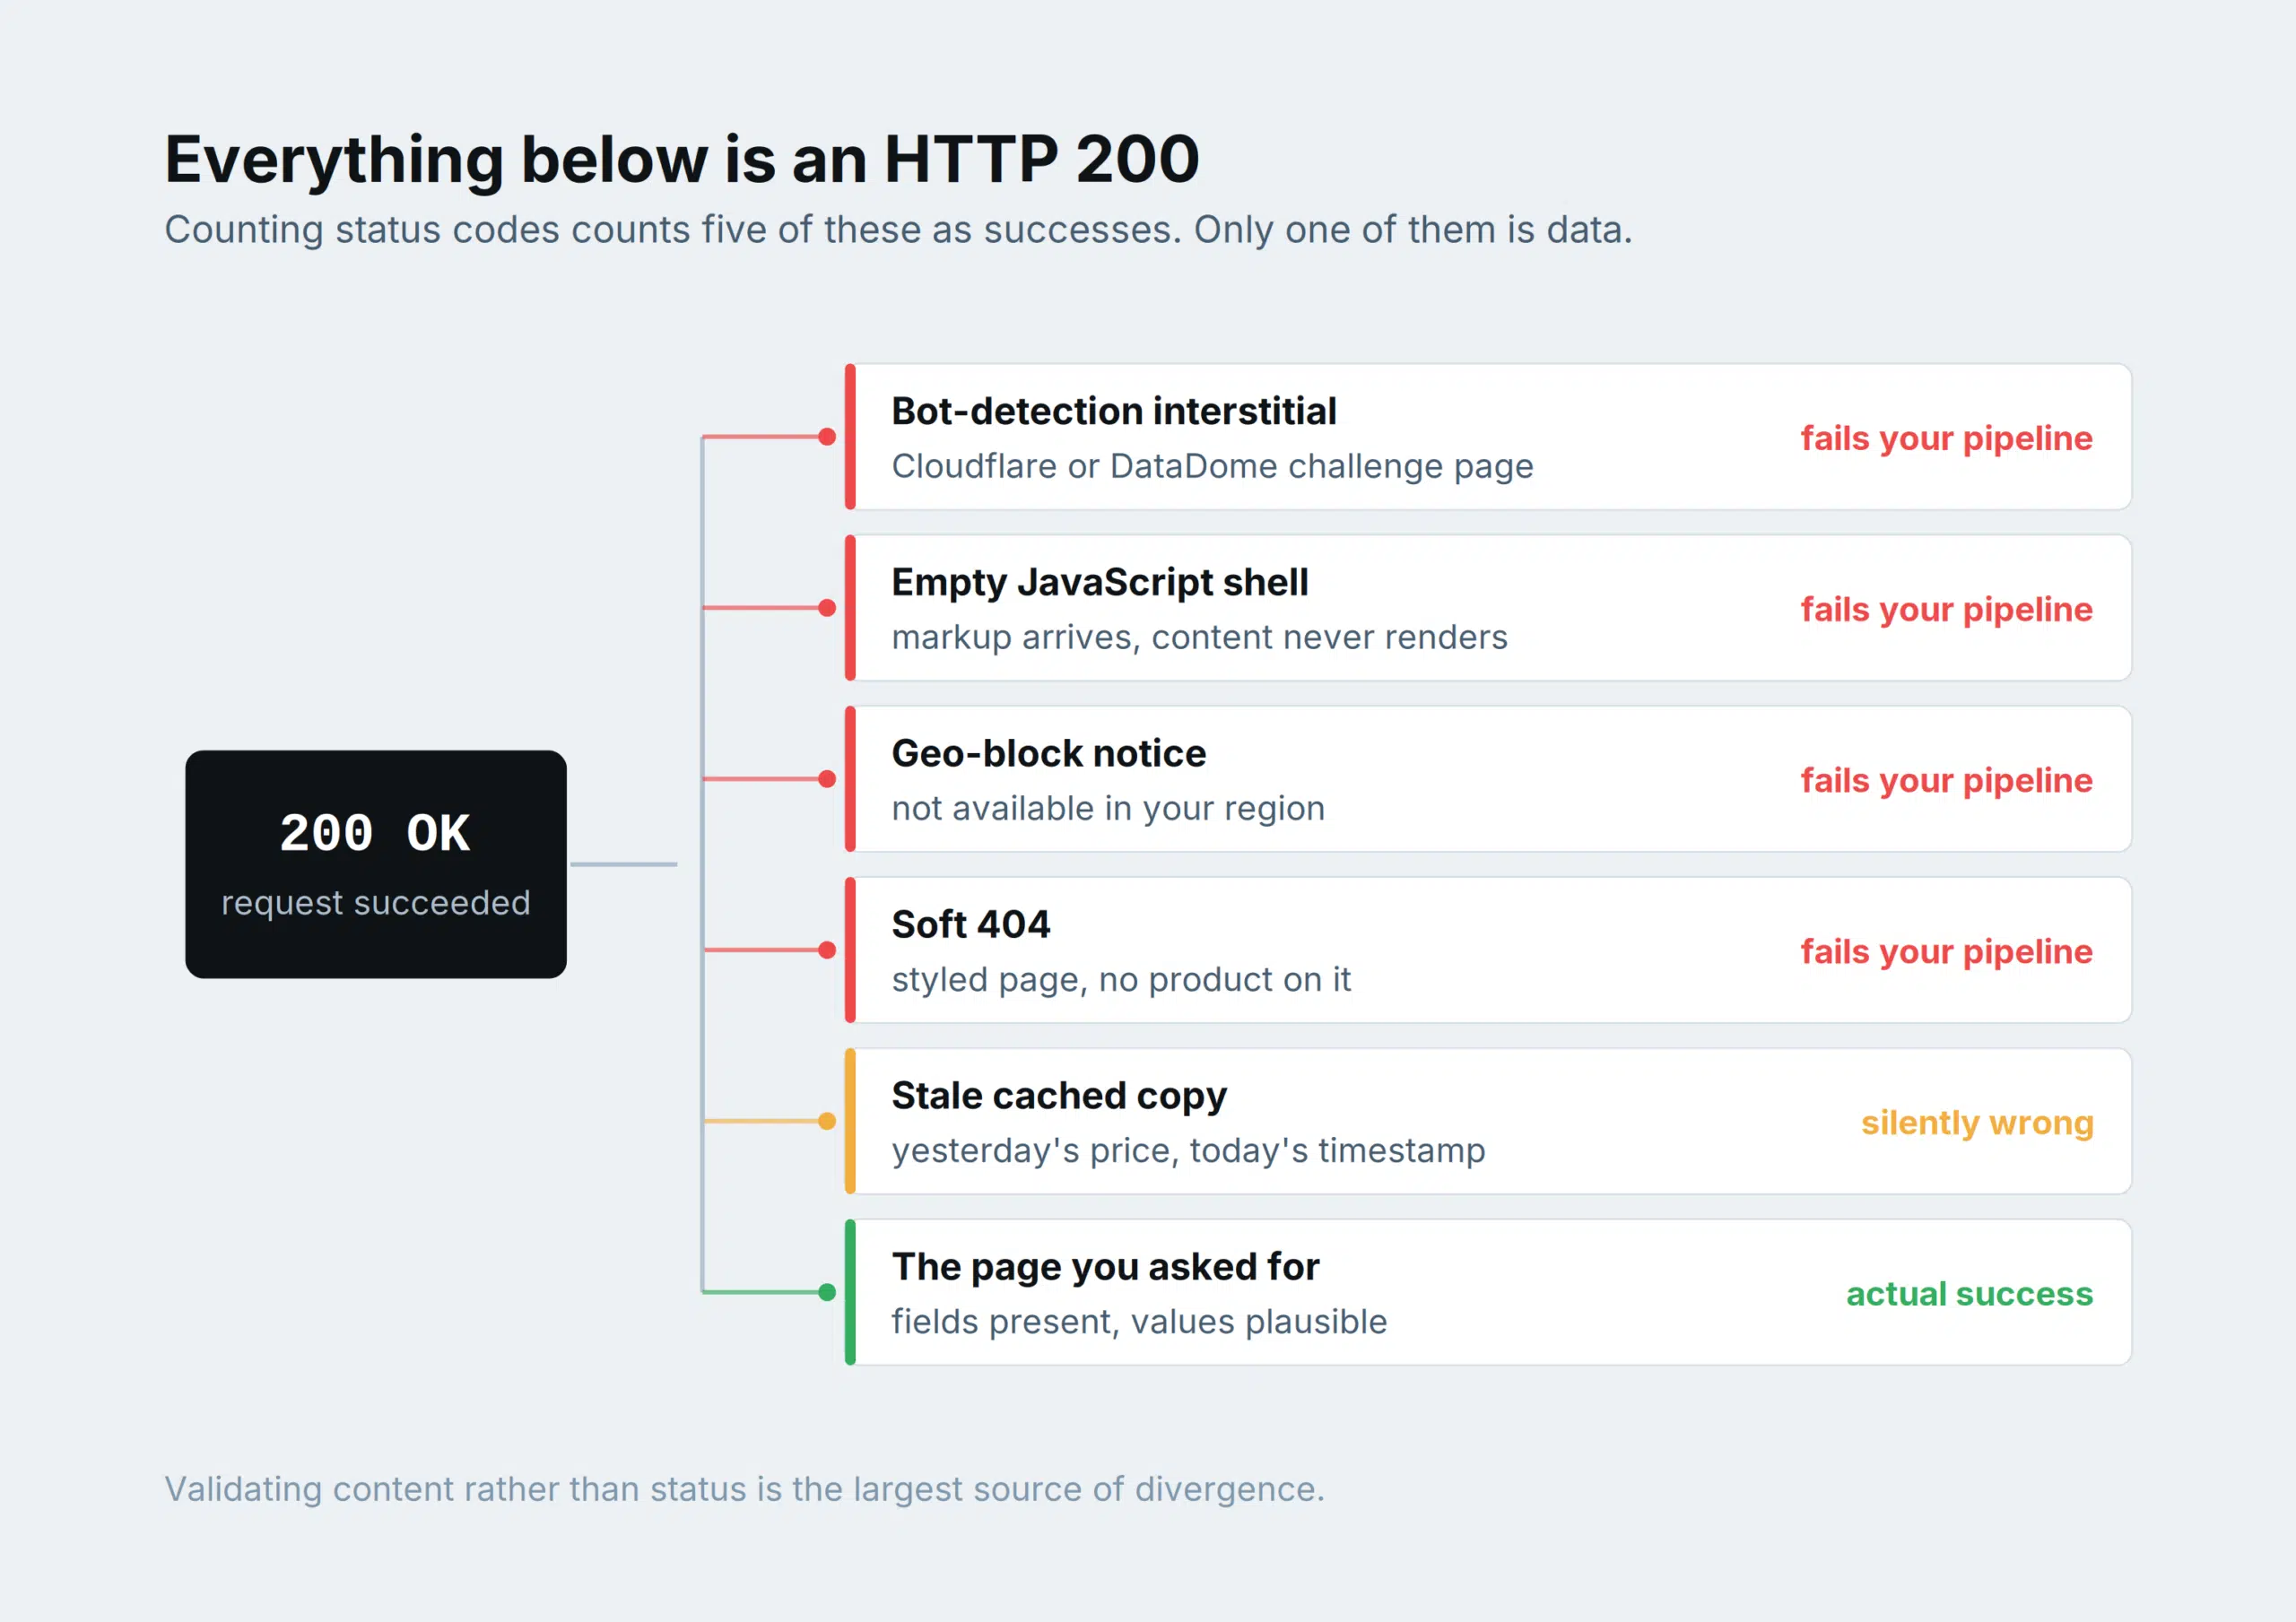
Figure 2. Status codes are cheap to count, which is largely why they get counted.
A defensible definition validates the body. One of the independent benchmarking publishers checks three things before calling a request successful: the response code, the response size, and the page title. That’s a reasonable floor.
For structured data, you want more, and you want it per field.
Of everything in this section, this is the biggest single source of divergence, and the gap has no fixed size.
On an ordinary protected site, two providers running identical infrastructure, one counting 200s and one validating fields, will report numbers tens of points apart.
On the hardest targets, the gap is the entire scale. Some large marketplaces answer essentially every request with a 200 and put a challenge behind it, so a status-code count reports 100% and a content-validated count on the same traffic reports close to nothing. Two numbers that share no digits, from one set of requests.
So there is no single figure for how much the definition is worth. That is the point. Anyone quoting a success rate without saying what they counted is quoting a number that could be off by anything up to the whole range.
Worth reading alongside our rundown of the most common web scraping errors, several of which return a 200 while delivering nothing you can use, and our explainer on what a bot blocker actually does to the response body.
3.2 Is the success rate before or after retries?
This is the one that surprised us the most, and it’s rarely disclosed next to the figure.
Suppose each attempt on a hard domain succeeds independently 60% of the time.
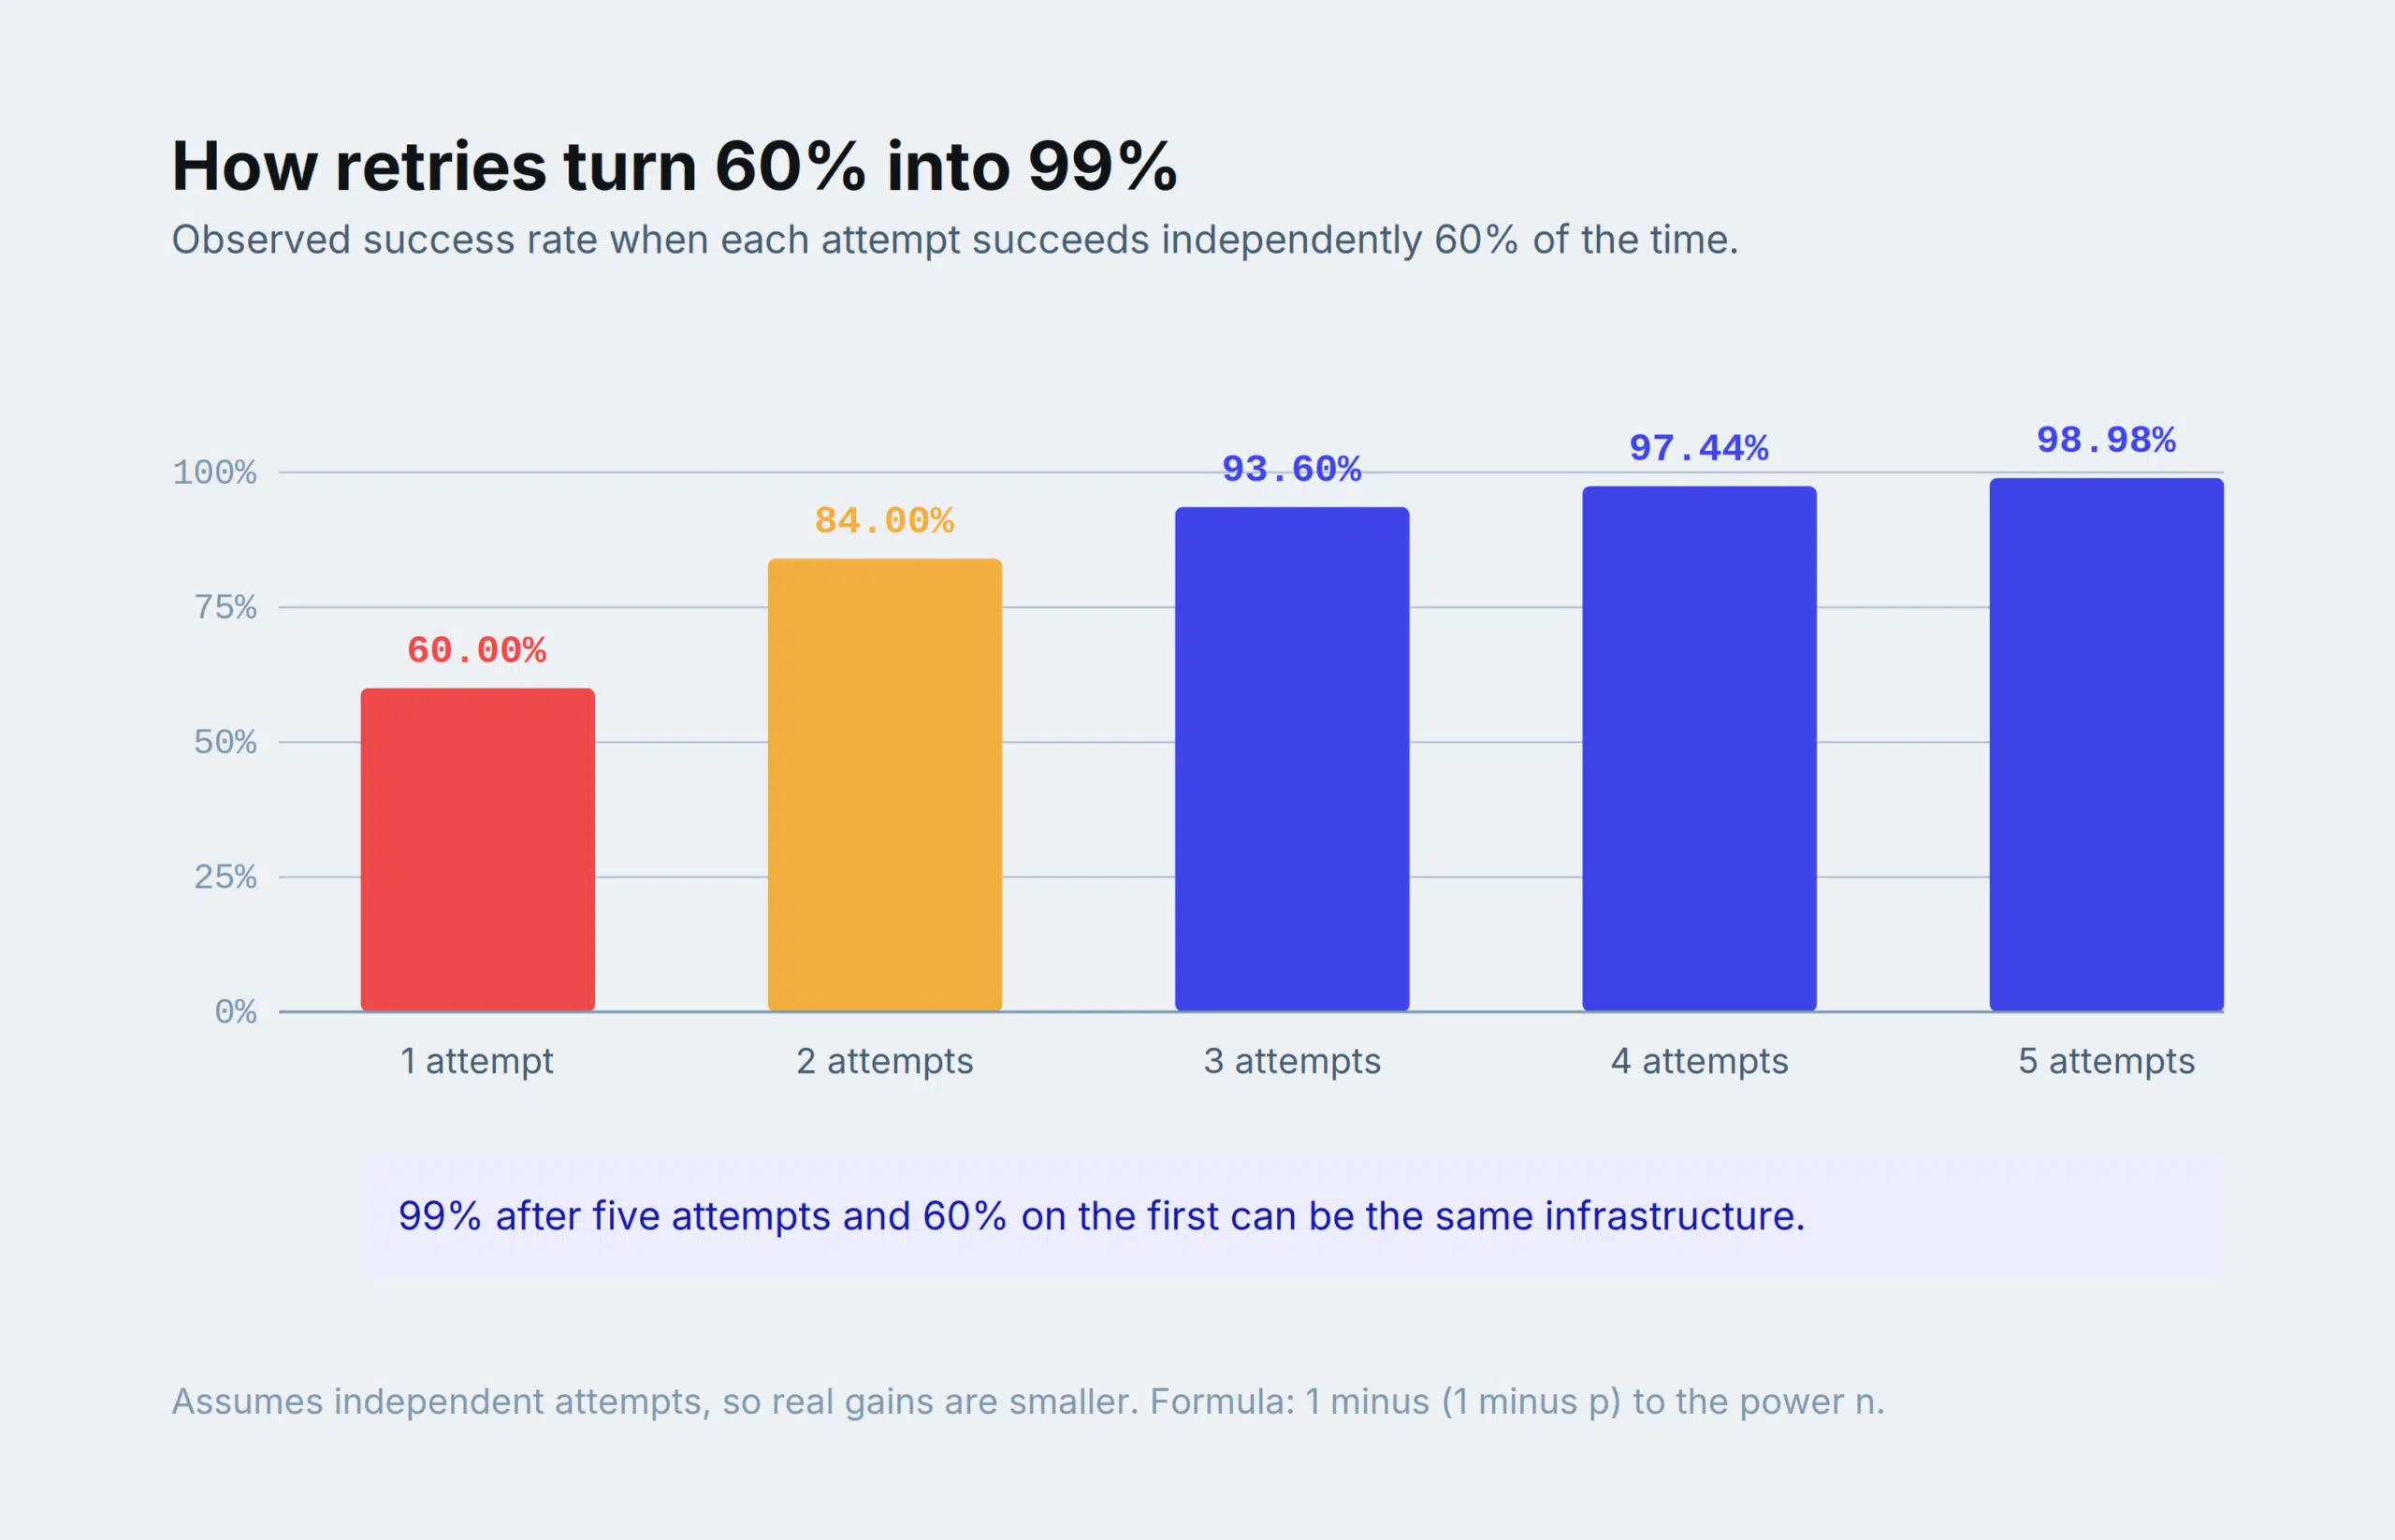
Figure 3. Five attempts at 60% each producing a headline of 98.98%.
A provider reporting 99% success after five attempts and a provider reporting 60% on the first attempt can be describing the same infrastructure, and both can be telling the truth. Only one of them looks good in a procurement spreadsheet.
Retrying isn’t cheating, to be clear. Retrying under the hood is most of what an unblocking product does, and hiding that complexity behind one API call is the entire value proposition.
Our own API retries for up to 70 seconds before it gives up, which is documented and deliberate. But a post-retry number quoted without its retry budget, and without the latency that budget costs you, is not something anyone can compare against anything. It amounts to a promise that you’ll get the page eventually, with “eventually” left blank.
3.3 Why success rate is different for every domain
Success rate is a property of a pair: this provider, that target, and not of the provider alone.
Independent benchmarks of scraping APIs make this obvious once you look past the summary row. The same provider comes out strong on some targets and weak on others, with per-target results inside a single report spanning tens of points.
Difficulty isn’t random either. It tracks which bot-management vendor a site has deployed and how aggressively it’s configured, which is why the practical unit of measurement is the domain, and sometimes the domain plus the request type.
A cross-domain average therefore says very little about your workload. If your pipeline is Amazon, Walmart, and Google, a number averaged over a basket that includes six sites you’ve never touched is noise with a decimal point attached.
For a sense of how much the target matters, see our breakdown of the page types that are genuinely hard to scrape and the main bot blockers in use, each of which behaves differently enough to move a per-domain number on its own.
3.4 How traffic mix changes a published success rate
A published average is partly a statement about the vendor’s customer base rather than its technology.
Take a service that gets 99% on easy targets and 55% on heavily protected ones. Its blended number is decided by the mix, and nothing else:
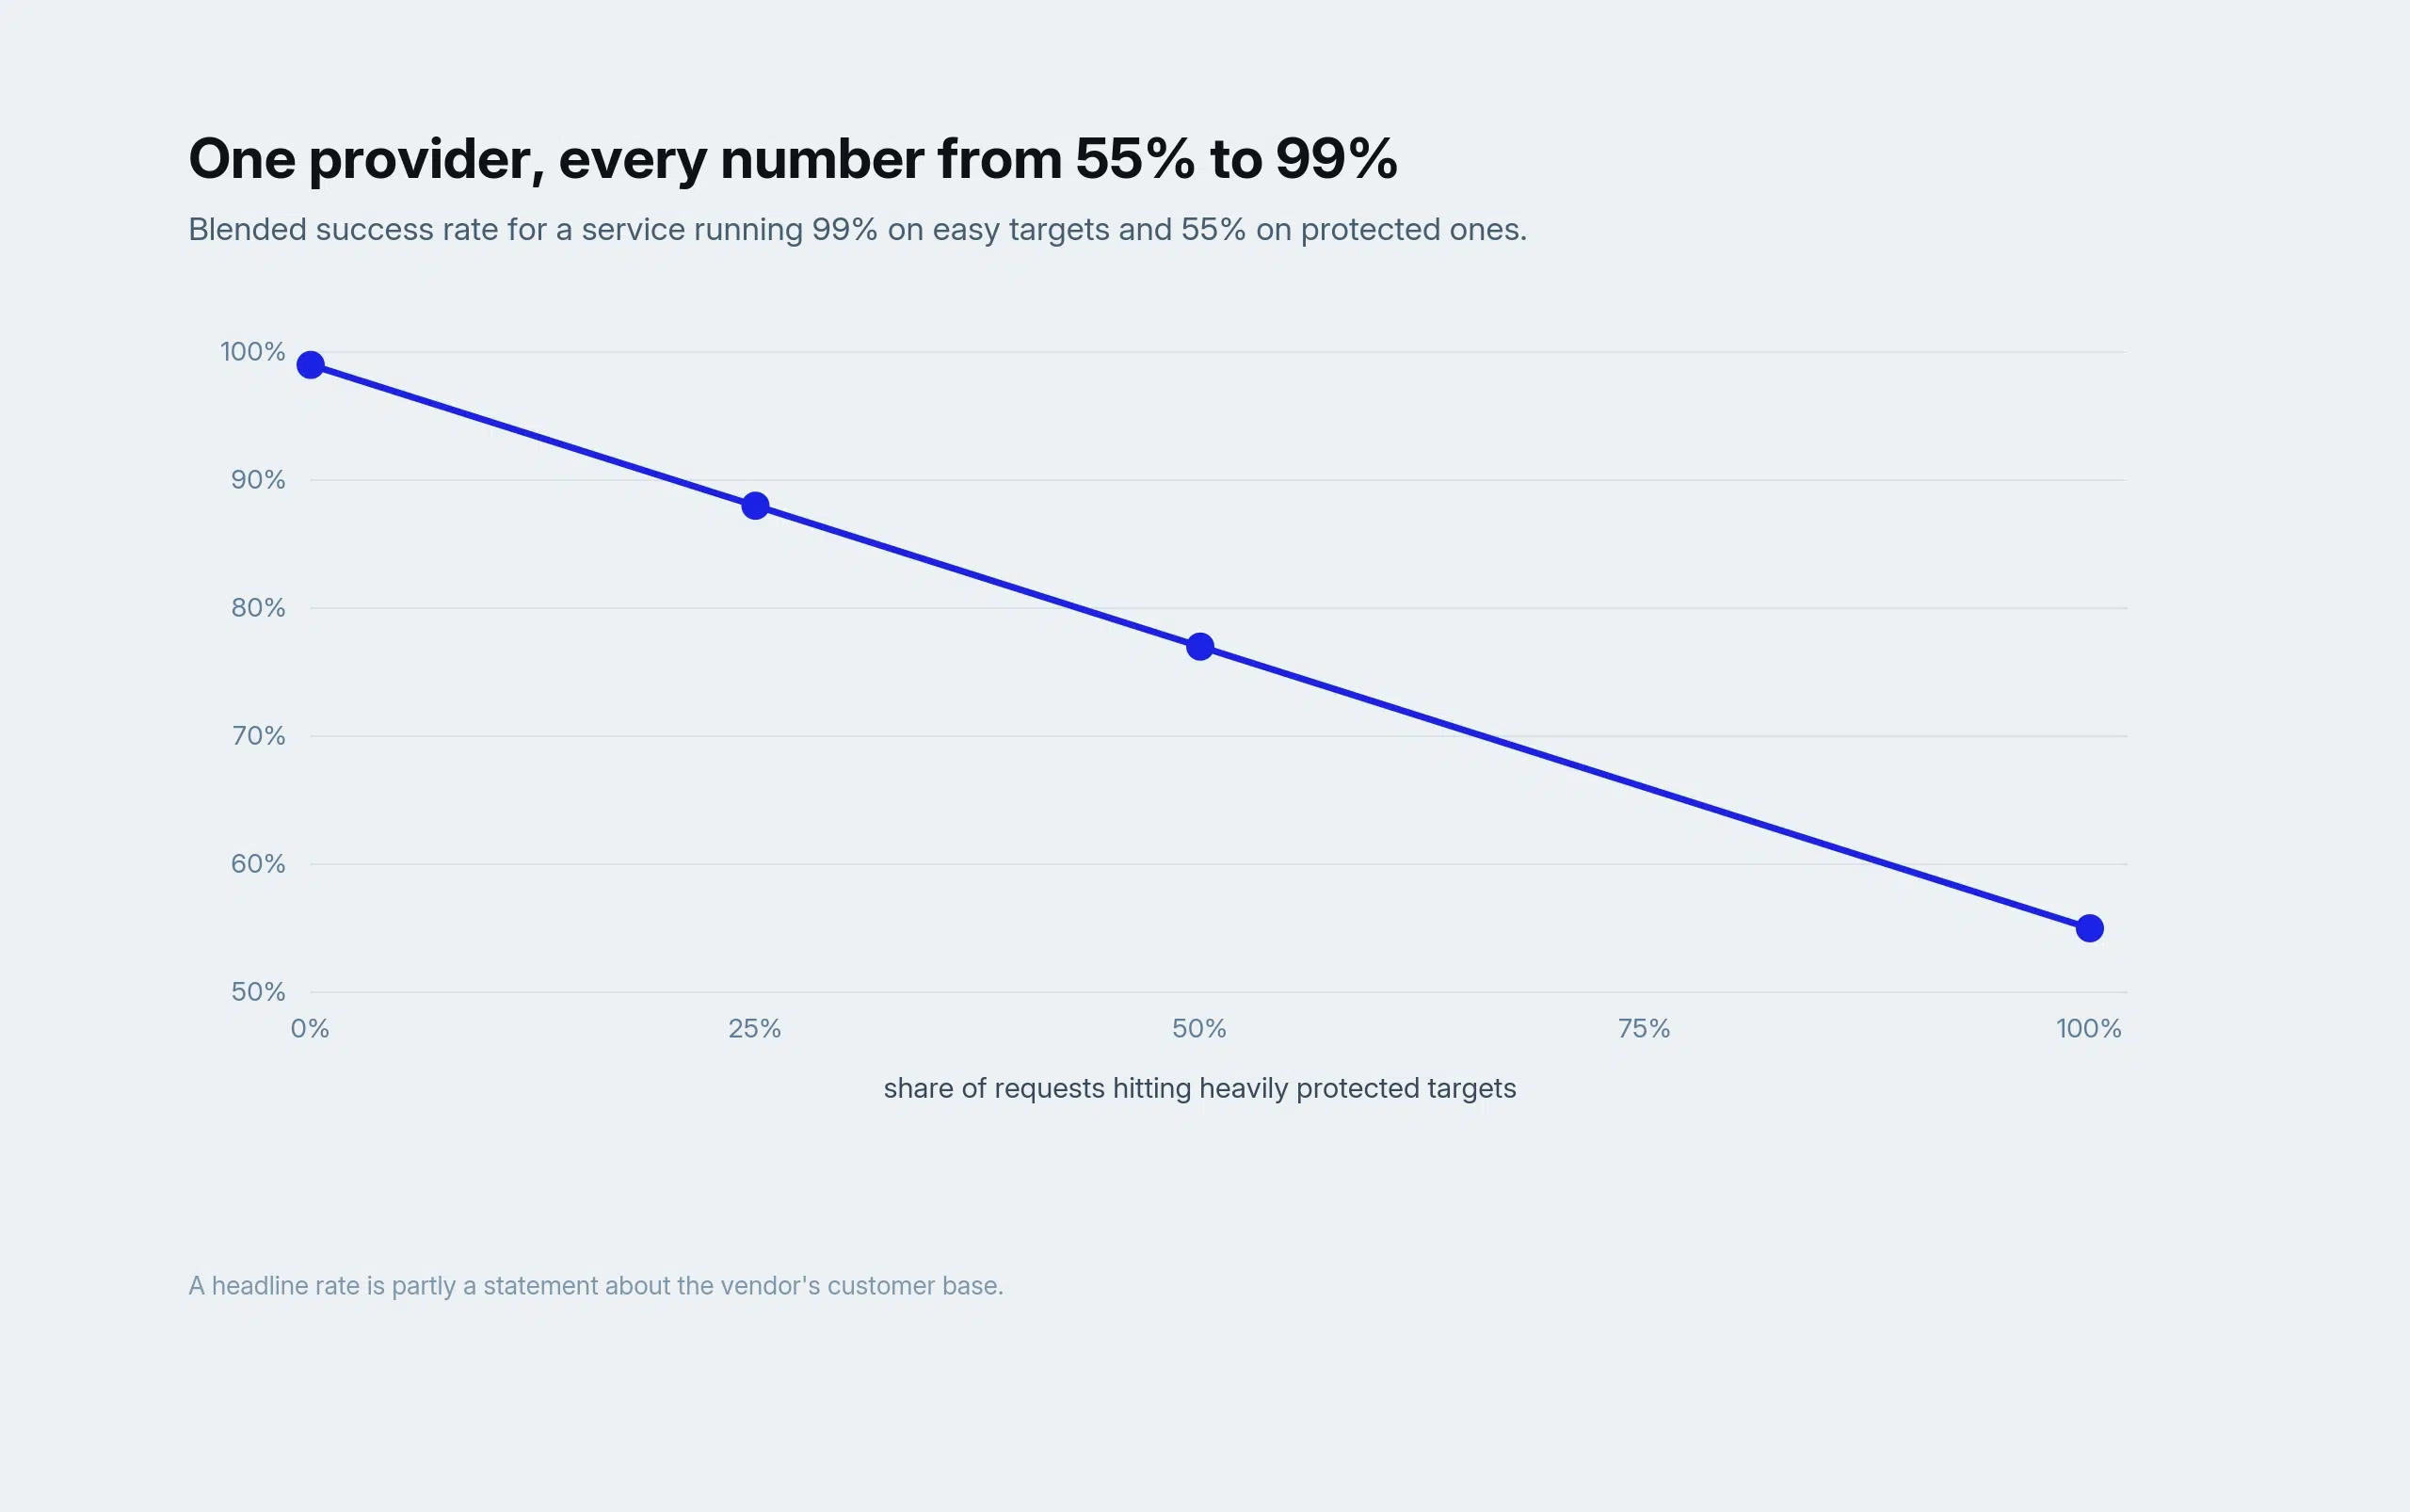
Figure 4. One service, 44 points of range, depending entirely on who its customers are.
Buy on a vendor’s blended average, and you’re assuming your traffic looks like their existing book of business. Sometimes it does. If you’re running SERP collection at scale and their average is dominated by ecommerce product pages, or you’re on real estate portals and they’re not, it doesn’t.
3.5 How many requests does a reliable measurement need?
A success rate is a proportion estimated from a sample, so it comes with an error bar. We have never seen one published.
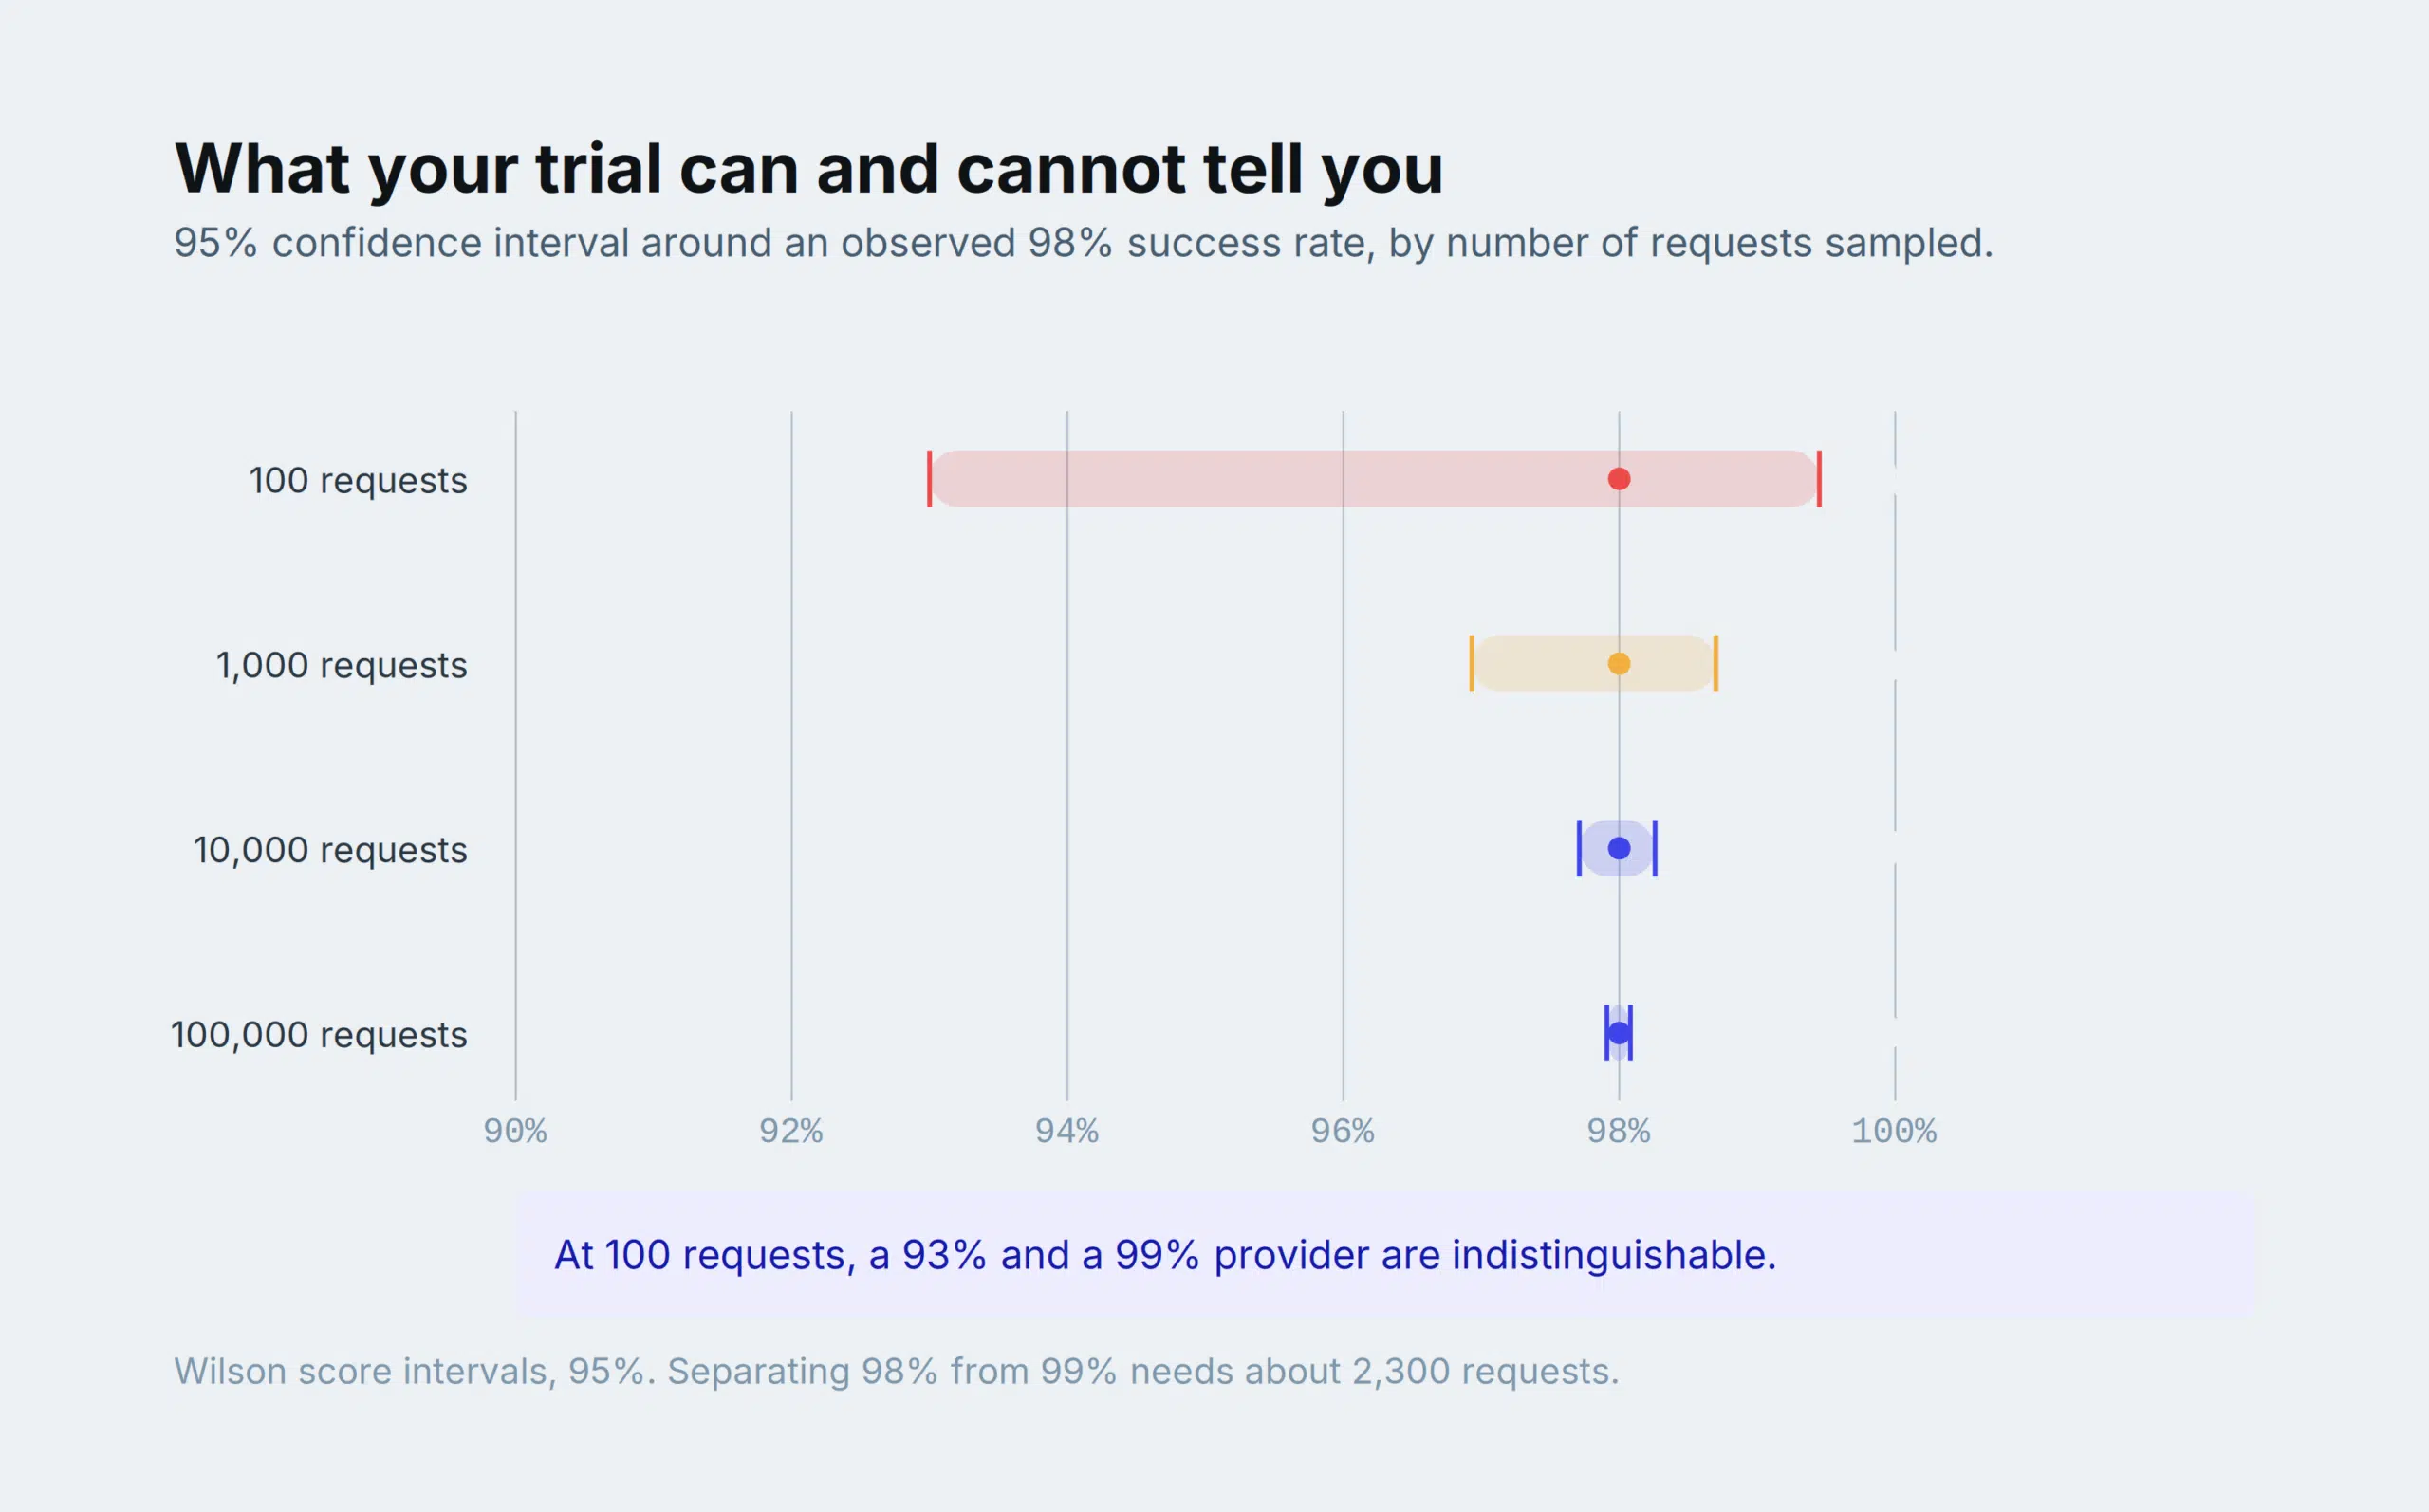
Figure 5. Wilson score intervals, 95%.
Two things follow. A 100-request trial cannot separate a 93% provider from a 99% provider, and a few hundred requests is roughly what most free trials give an evaluator before they make a decision.
And most published comparisons cannot support the distinctions they draw: telling 98% from 99% at conventional standards needs about 2,300 requests per provider on the same targets, and telling 99.9% from 99.95% needs about 47,000. When a table ranks eight providers to one decimal place, the question worth asking is how many requests sat behind each cell.
Time matters as much as volume. Anti-bot configurations change. A domain that ran at 97% last month can sit at 60% this week because the site deployed a new challenge, then recover a fortnight later once the provider adapts. Any figure without a window attached is outdated, and outdated reliability figures age badly. Our guide to bypassing bot detection goes into what actually changes on the target’s side.
3.6 How success rate and latency trade off against each other
Success rate and response time aren’t independent variables. You can buy success with retries, rendering, and residential routing, and you pay in seconds.
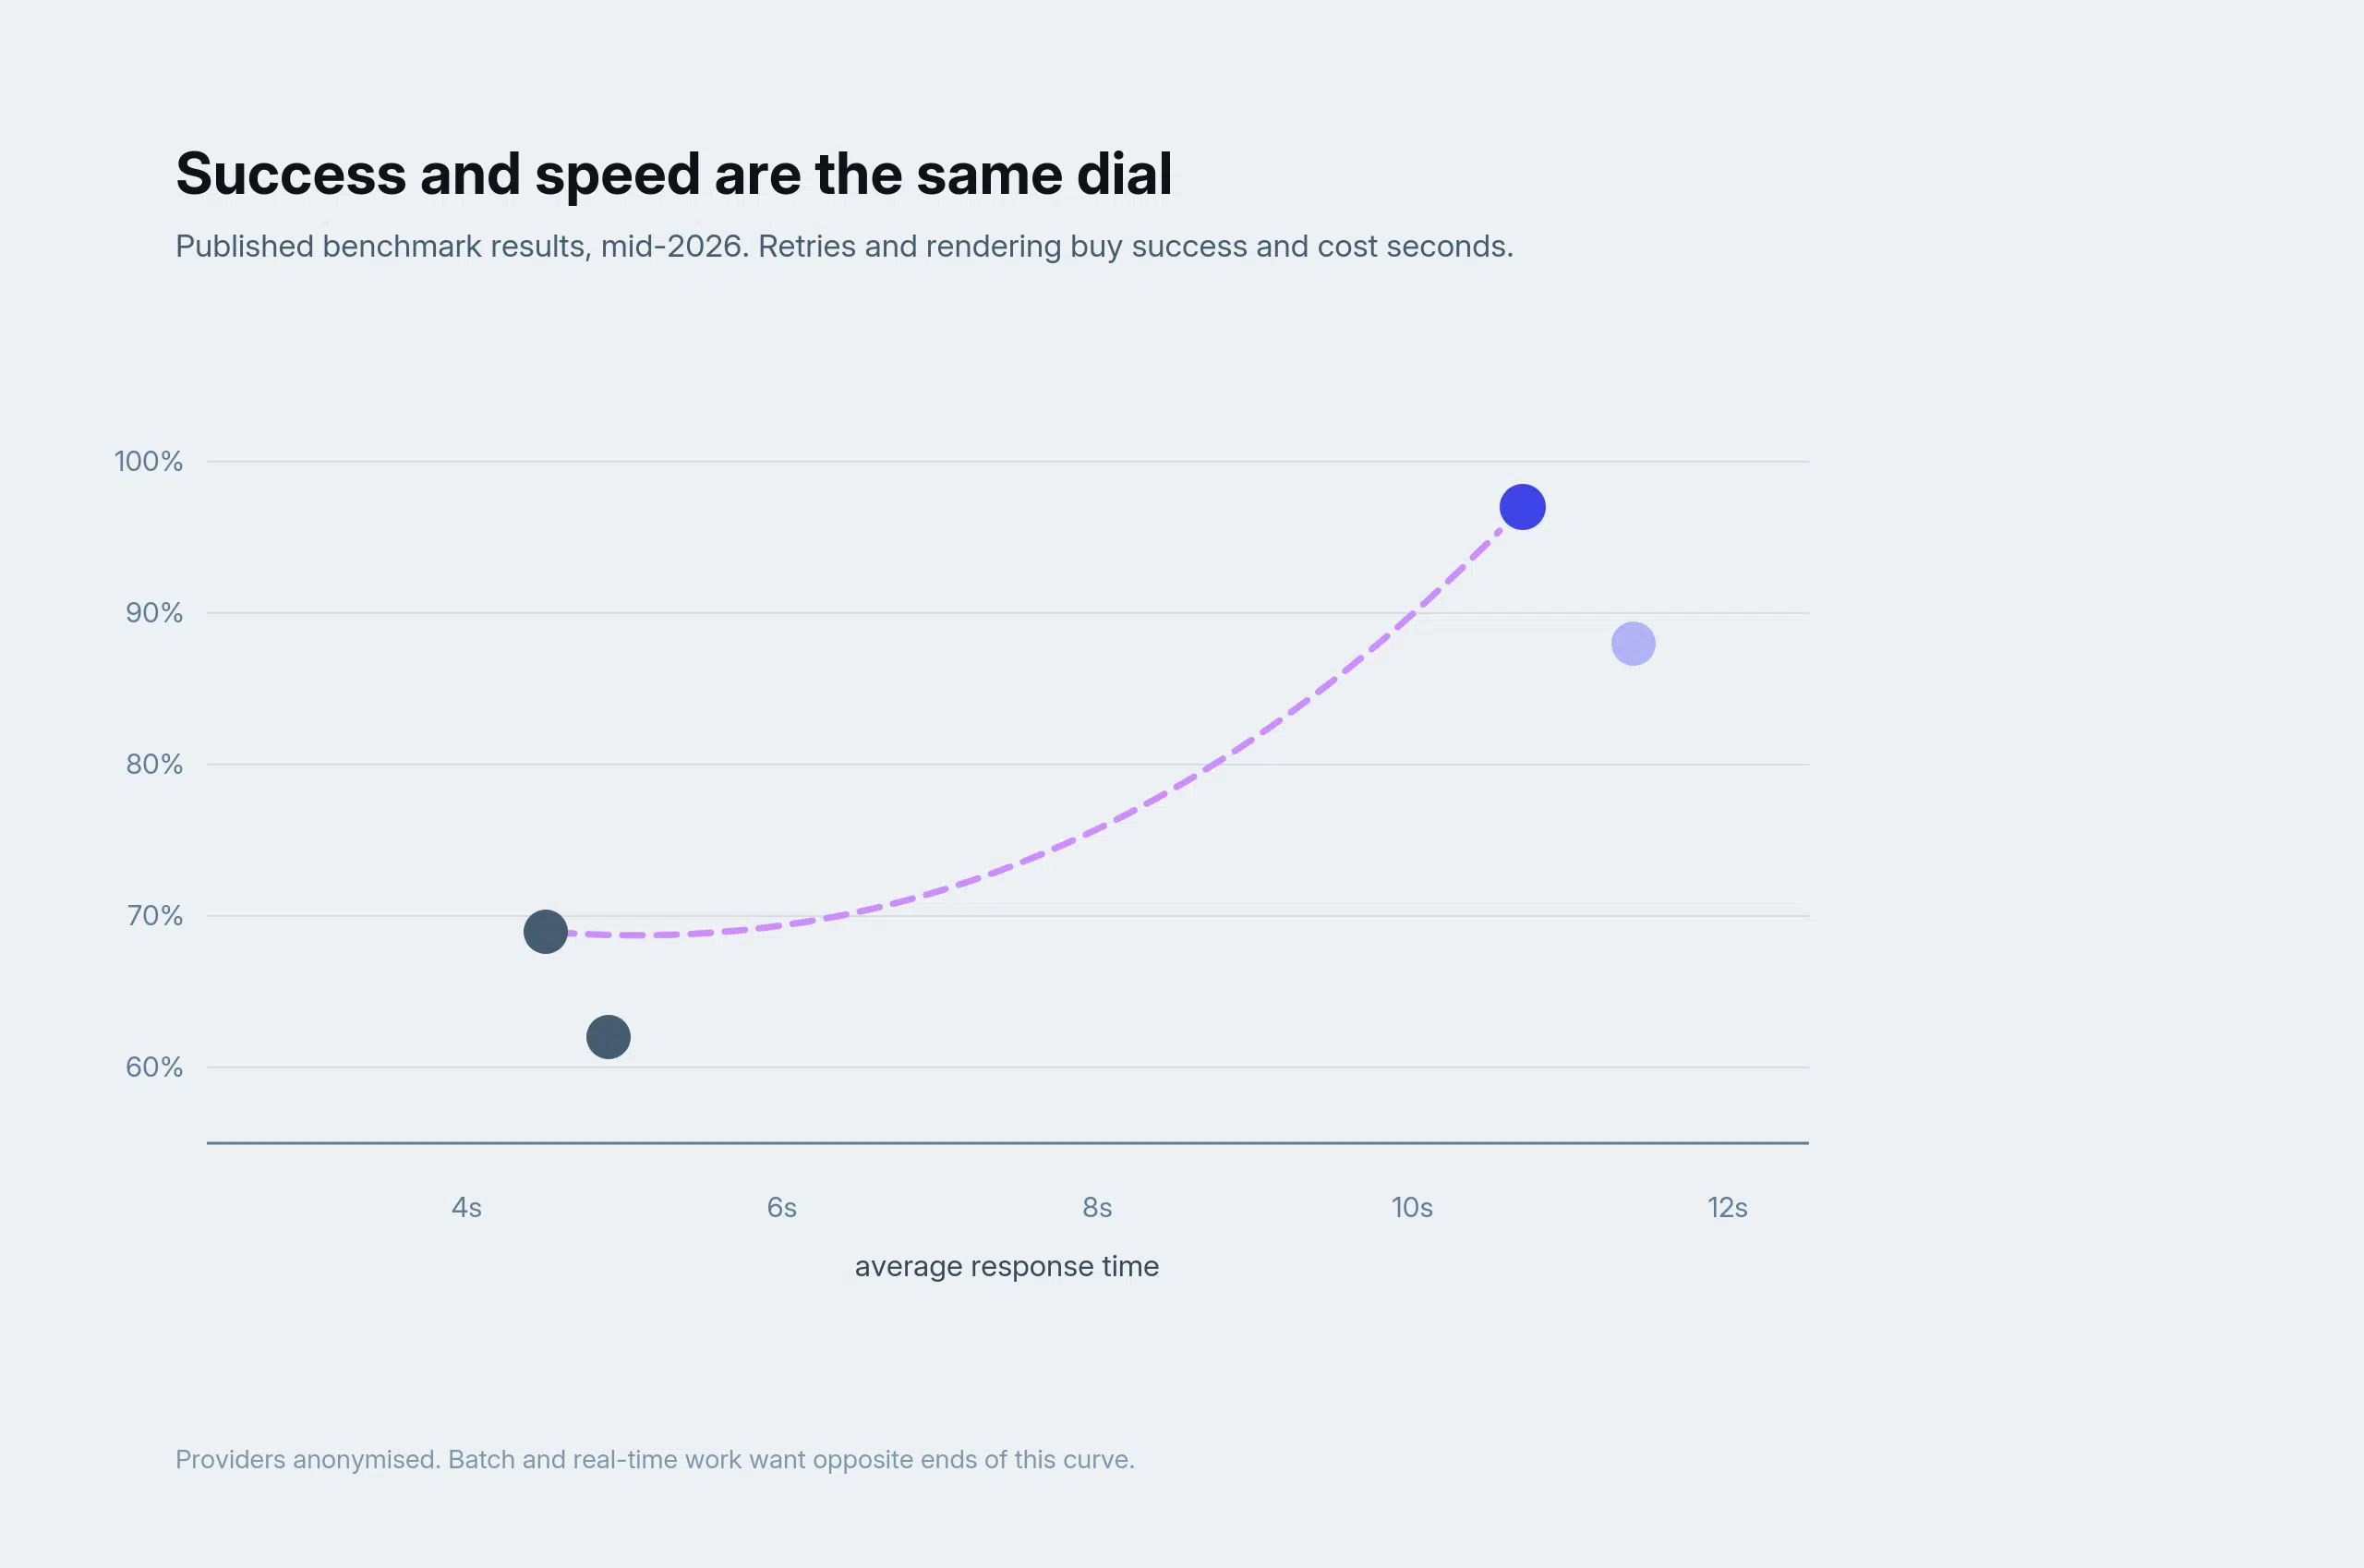
Figure 6. Mid-2026 published benchmark results. Not a ranking.
In one benchmark family’s mid-2026 runs, the top-scoring API returned about 97% success at roughly 10.7 seconds average, while another managed about 62% at 4.9 seconds. Neither is simply better than the other. They’ve been tuned to different points on the same curve, and which point is correct depends on whether you’re doing a real-time lookup or an overnight batch.
If your workload is the latter, our async scraper service exists precisely so you can trade latency for success without your client sitting there holding the connection.
Publishing one without the other lets a provider pick whichever end of the curve flatters it, which is the most common way a technically true reliability number ends up misleading.
4. How to define a reliability metric: SLI, SLO
Site reliability engineering settled this argument twenty years ago. Our industry just hasn’t picked up the words.
The standard framing keeps three things apart:
- SLI, service level indicator: A defined quantitative measure, usually good events over valid events, or a percentile of a distribution.
- SLO, service level objective: A target for that indicator over a stated window.
One caution before you use any of it. This vocabulary is for reading what other people publish. It is not a template for what a scraping provider should promise. An objective is a commitment, and a commitment about reaching third-party websites is a commitment to keep winning a contest against companies with far more engineering capacity than any data provider has.
The useful discipline lives in the indicator. You have to define good, you have to define valid, and you have to say how the measurement is taken.
Google’s SRE guidance separates the specification (the outcome you believe matters) from the implementation (the specification plus the mechanism that measures it). Most reliability claims in web scraping have neither, which is why they can’t be checked.
The second thing worth stealing: for anything time-based, use percentiles rather than averages. This isn’t stylistic. A distribution where most requests are quick and a minority are very slow produces a comfortable mean sitting next to a p99 an order of magnitude higher, and it’s the p99 that decides whether your job times out. Averages also can’t be recombined, so averaging per-region p99s gives you a number that is the p99 of nothing at all.
5. How to measure web scraping reliability: The four metrics
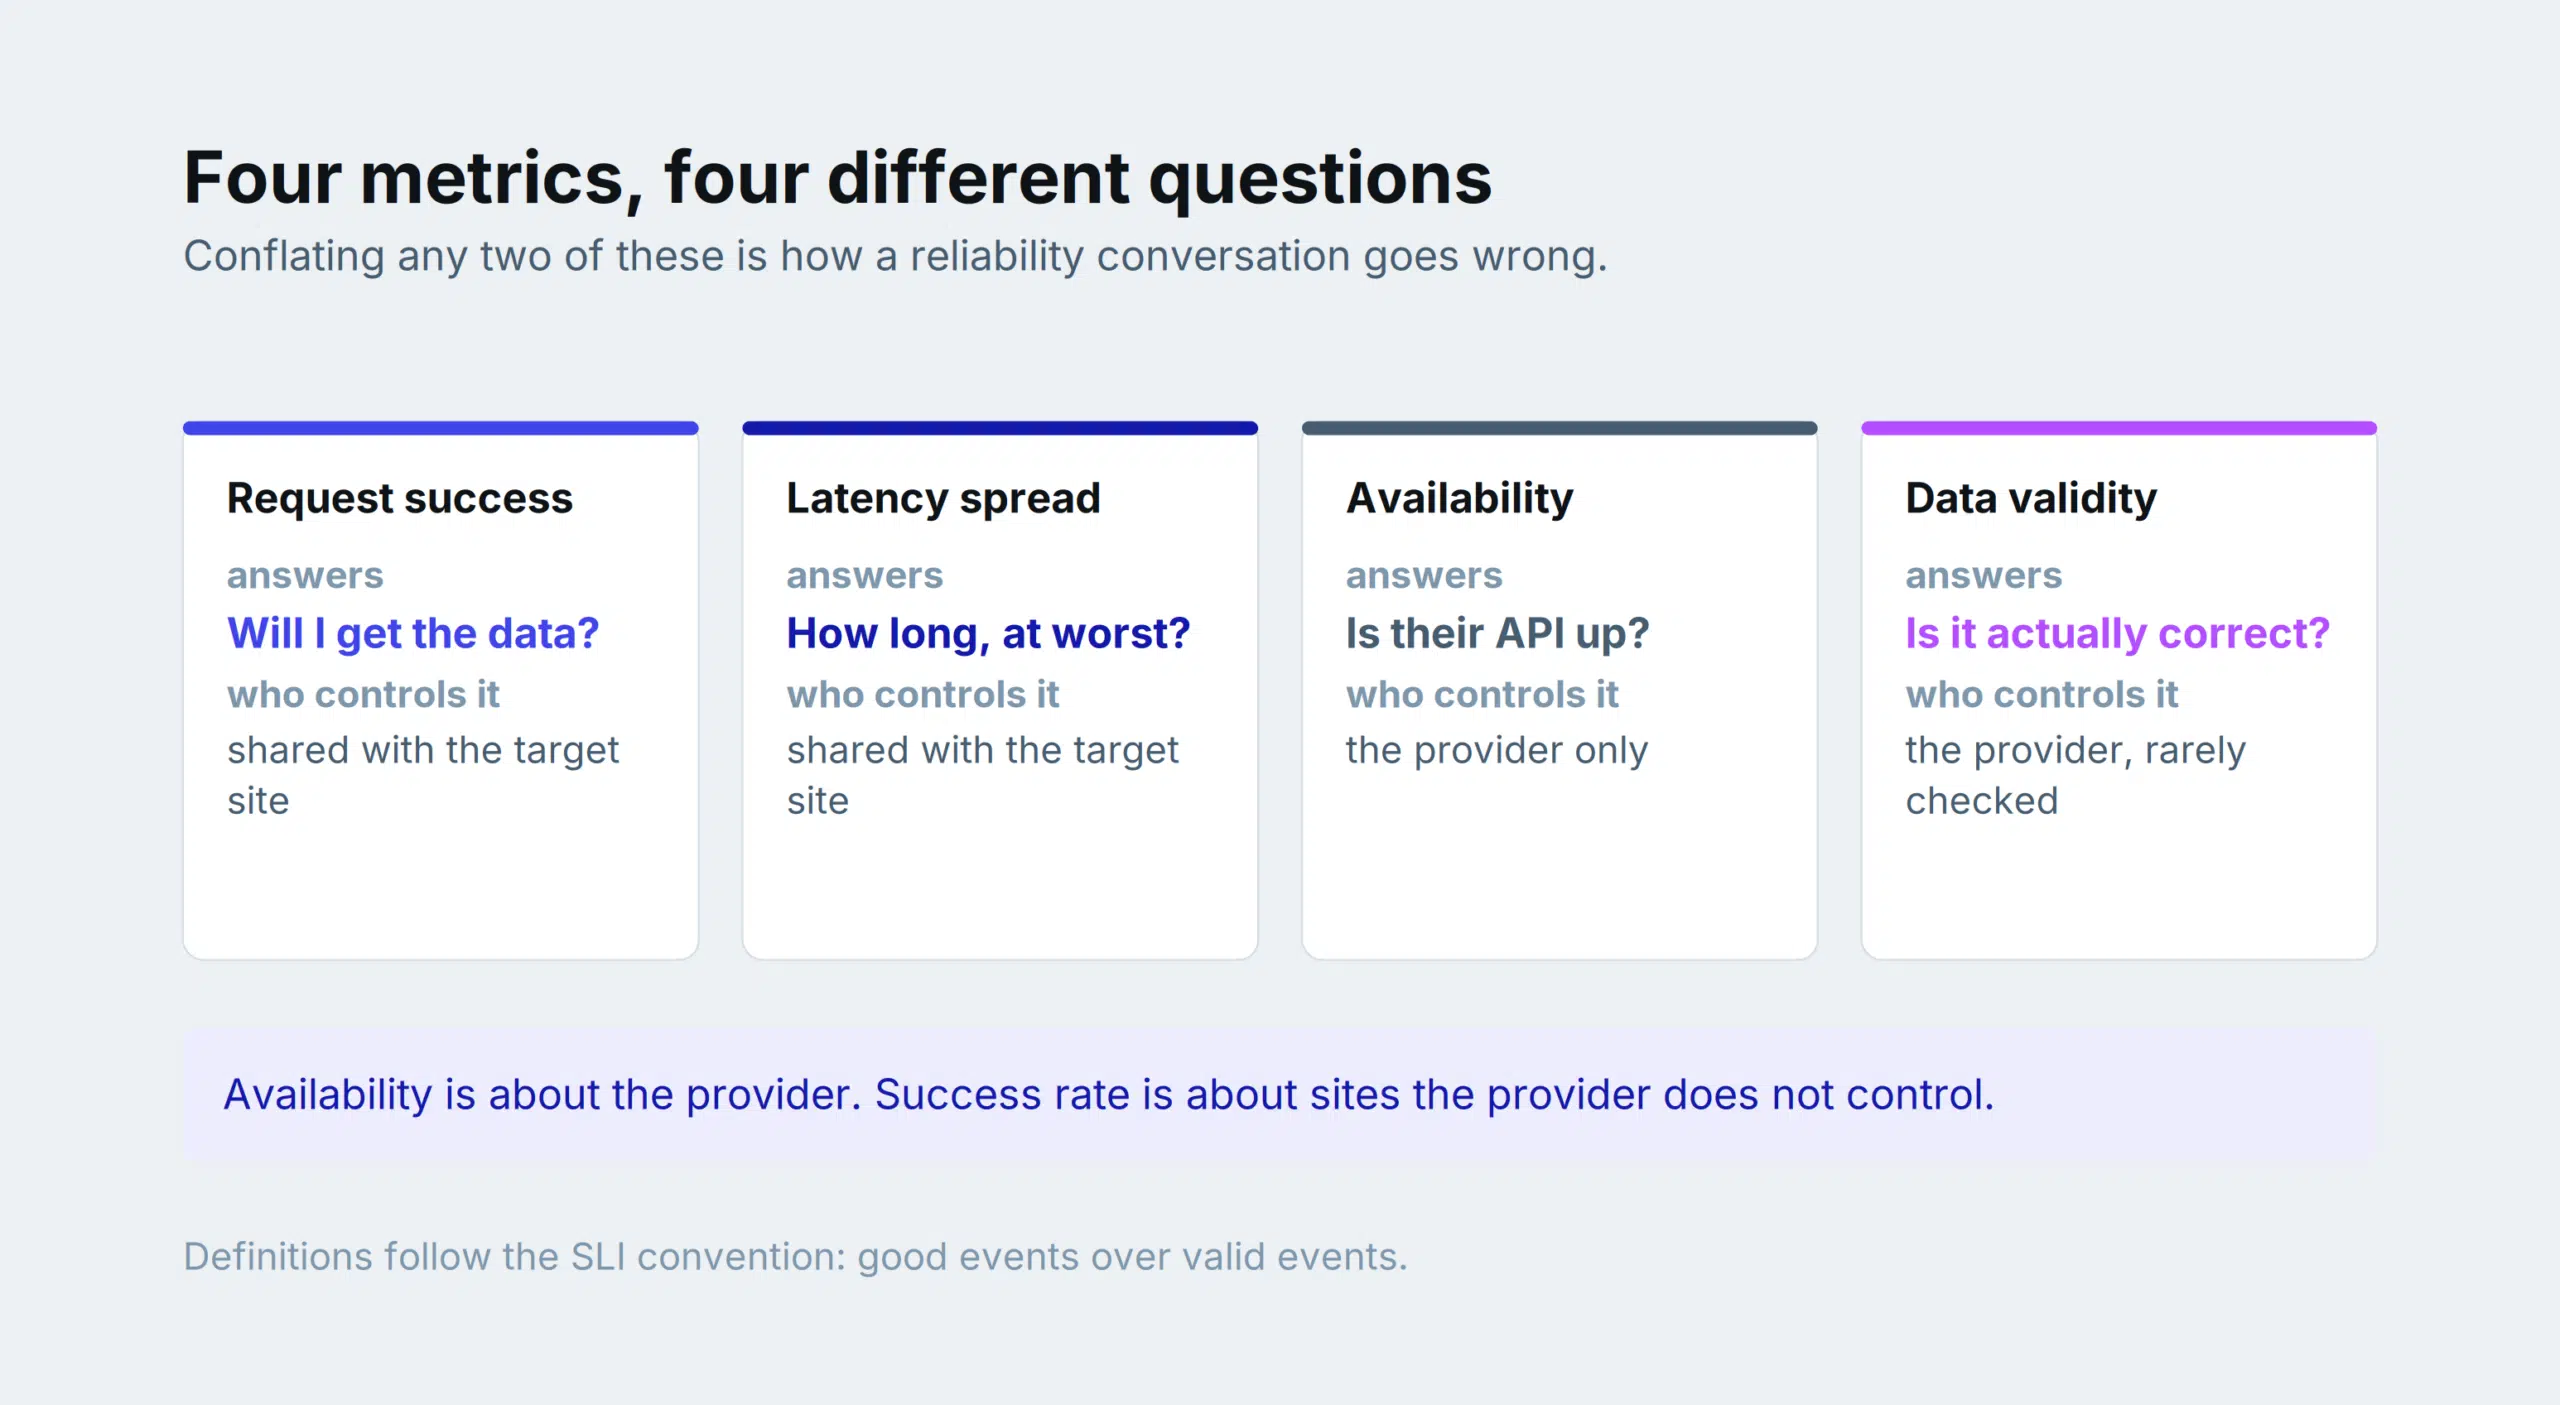
Figure 7. Conflating any two of these is how a reliability conversation goes wrong.
5.1 How to define request success rate
Ask for valid responses over total attempted requests, where “valid” means content checks rather than status codes, measured per domain, over a stated window, with the retry policy attached.
That definition does the work. Ask for the number two ways as well, but be clear about why: these are not separate metrics competing for space on a dashboard.
They are the same metric with the retry question answered differently, and each one is really reporting on something else.
| What you ask for | What it is actually telling you |
|---|---|
| Success rate including retries | Whether you will get your data at all. The headline figure, and the one most vendors publish |
| Success rate on the first attempt | What the data costs you. A wide gap between this and the figure above means heavy retrying, which shows up as latency and as credits |
The second row is worth asking for even though it is not really a reliability number. It is a latency and cost number wearing a reliability costume, and reading it that way keeps you from double-counting.
Two other things anchor this metric, and without them the percentage floats free.
- Upward, to the success definition in section 3.1. If the denominator counts status codes, the figure describes transport rather than data, and a challenge page counts as a win.
- Downward, to data validity in section 5.4. A response can pass every content check and still carry a stale price or a truncated field.
Success rate sits between those two and borrows all its meaning from them. A provider who quotes it without pinning both is quoting a number that cannot be checked, however large it is.
5.2 Why latency needs p50, p95 and p99 rather than an average
Ask for: p50, p95 and p99 of end-to-end response time, per domain, retry policy stated, over the same window as the success rate.
The median gives you typical behaviour, p95 is your early warning, and p99 is the number your job timeout has to survive. If a provider retries internally for up to a minute, their p99 on a hard domain is measured in tens of seconds and their average won’t hint at it. Ours doesn’t, which is why our docs tell you to set a 70-second client timeout rather than leaving you to discover it.
One question people forget: Does the published latency include failed attempts? A figure computed over successes only runs optimistic, because failures are usually the slow ones.
5.3 Uptime versus success rate: what is the difference?
Ask for: the proportion of a stated window in which the API accepted requests and returned responses, measured externally, backed by a public status page and an incident history you can read.
Availability and success rate get used interchangeably constantly, and they are not the same thing. Availability describes the provider’s own service. Success rate describes third-party websites the provider doesn’t control. A provider can be fully available and return failures all afternoon because a target rolled out a new challenge. Only one of those two things is within their control, and answering a data-access question with a server uptime number is a way of not answering it.
Then be careful what anyone does with the answer, including us.
Availability is the metric here that a provider should be slowest to turn into a promise, and that a buyer should read with the most suspicion.
Everyone in web data collection works in an adversarial relationship with some of the largest engineering organisations on earth, and those organisations can put effectively unlimited resources into keeping automated traffic out if they decide to. A vendor who commits to an availability figure for data access is committing to keep winning that contest, continuously, against opponents who are under no obligation to stand still.
Nobody can honestly promise that. What a provider can promise is the availability of its own API, which is a much narrower thing: Our servers accepted your request and answered it. That commitment is reasonable and measurable, and it says nothing at all about whether a particular retailer let us in this morning.
So when a provider quotes availability, the first question is not how many nines. It is which of those two things the number covers, and which one appears in the contract.
What the nines buy you, per 30-day month:
| Availability | Downtime it permits |
|---|---|
| 99.0% | 7 hours 12 minutes |
| 99.5% | 3 hours 36 minutes |
| 99.9% | 43 minutes |
| 99.95% | 22 minutes |
| 99.99% | 4 minutes 19 seconds |
| 99.999% | 26 seconds |
Treat five nines on a service that depends on the public internet and on third-party websites as a marketing number rather than an engineering commitment. Twenty-six seconds a month is not a promise anyone in this category should be making casually, ourselves included, and section 10 is where we deal with the fact that we have.
What is worth more than the percentage is the record. An incident history is backward-looking and checkable: it says what happened, and you can hold it against your own logs. An availability objective covering data access is forward-looking and, for the reason above, unkeepable.
Ours is at status.scraperapi.com, and the question worth asking about any status page is who updates it: automated health checks or a human after a customer complains.
5.4 Data validity and silent data degradation
Ask for the proportion of successful responses containing complete, correct, current target data, verified by field-level checks against a known baseline.
Nearly nobody publishes this, and it causes more damage than the rest combined, because it fails silently.
The response arrives, it’s a 200, the size looks right, the pipeline ingests it, and the price field is stale or empty or wrong. Nothing alerts. You find out days later, in your product, in front of a customer.
The teams we talk to who run serious pipelines have almost all built their own validation layer on top of a vendor at some point, usually after a degradation their own monitoring caught and the vendor’s didn’t. That’s a rational response to an industry that measures transport success and calls it reliability.
Checks worth demanding, or building:
- Presence: Are the required fields there at all?
- Plausibility: Is the price a number in a sane range, is the timestamp recent?
- Consistency: Does today’s record for this SKU differ from yesterday’s in a way that makes sense?
- Coverage: For a catalogue of known size, what proportion came back?
- Drift: Has the schema, or the population rate of a field, changed quietly?
If you’d rather not own this layer, structured data endpoints move the schema maintenance to the provider’s side, which changes who is responsible when a site redesigns but doesn’t remove your need to check.
6. Per-request versus per-job success rate
Per-request success compounds. The figure providers publish describes one request. What you care about is whether a job finishes.
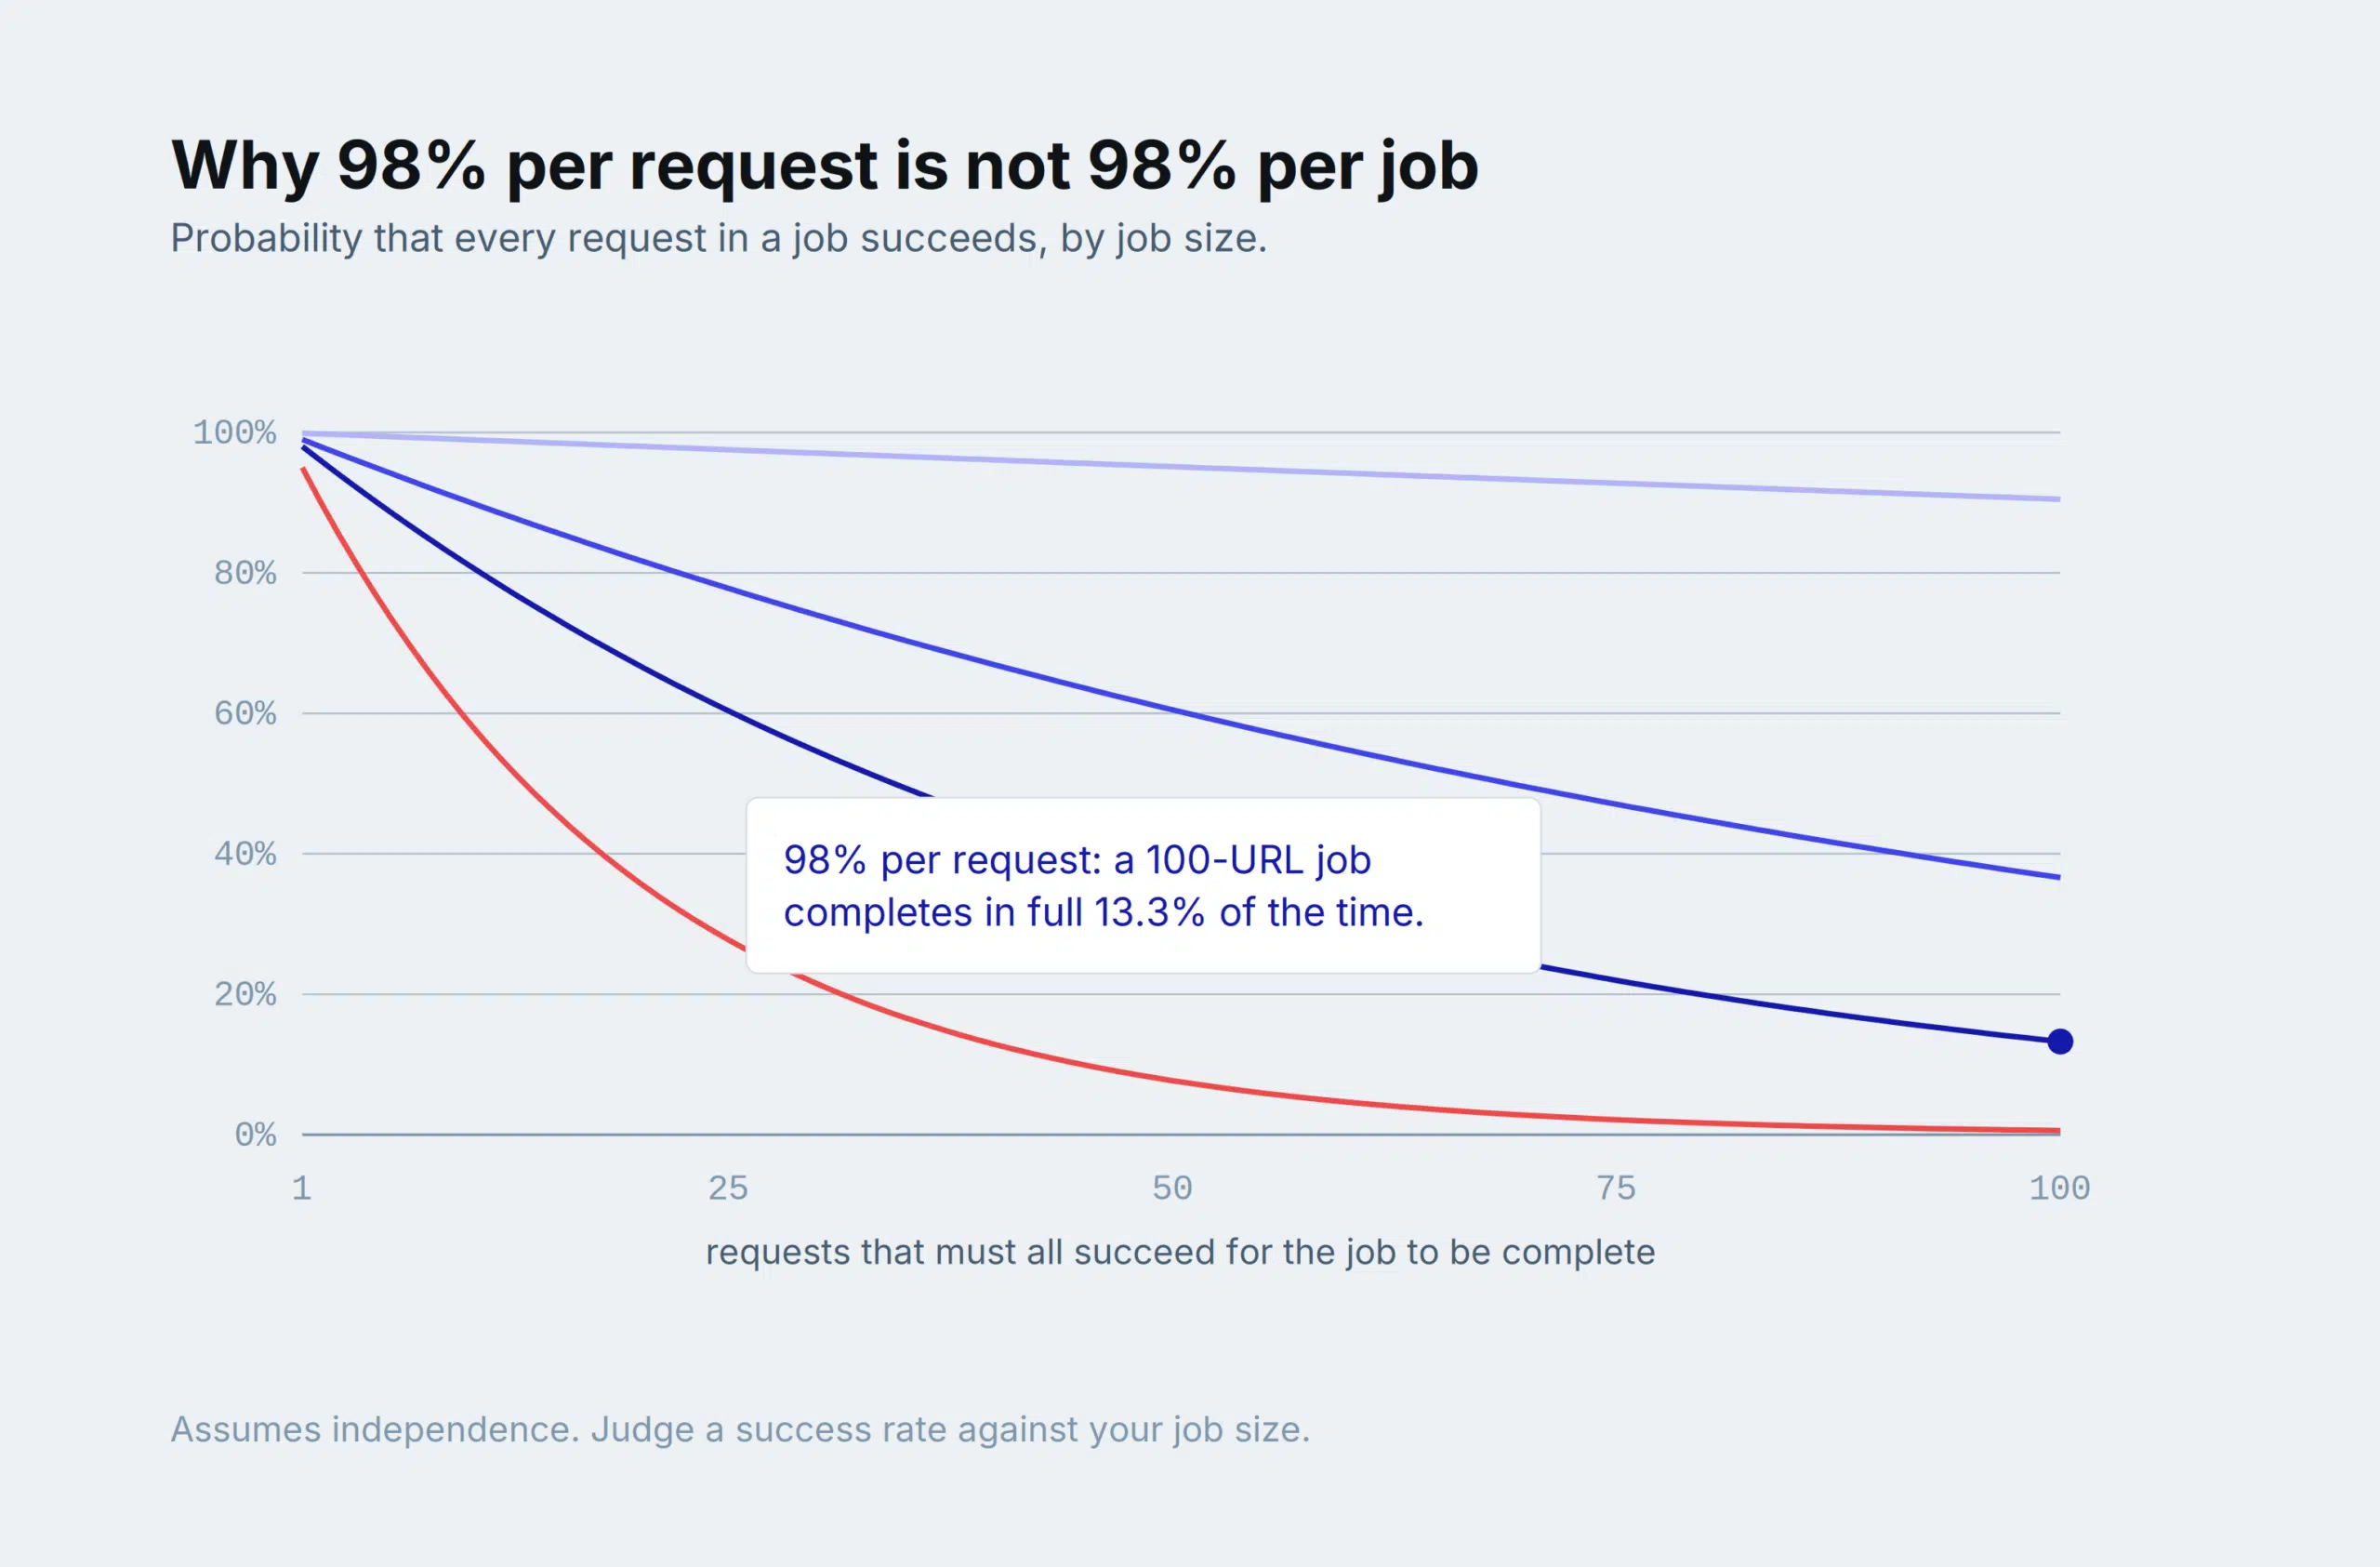
Figure 8. Every request in the job has to succeed for the job to be complete.
At 98% per request, a 100-URL job comes back complete 13.3% of the time. That isn’t an argument against 98%, which is a good number, and it isn’t a fifth metric to go and ask a vendor for. It is what a success rate already means once a job contains more than one request. Anyone with a good success rate has a good job completion rate, by construction. What the table shows is that good has to be judged against your job size rather than in the abstract.
Which lens you need depends on your unit of work, so decide that before you evaluate anyone. If partial results are fine, per-request success is the right measure and 98% is strong. If you need the full basket, a complete catalogue snapshot, or an entire keyword set with no gaps, then the metric is job completion rate, and you should ask for it by name. Most providers won’t have it to hand. That in itself tells you something, and it’s part of why batch and pipeline tooling tends to report at the job level rather than the request level.
7. Seven things every reliability figure must state
A published reliability figure needs to state seven things. Short of that, it can’t be compared with any other figure, and it shouldn’t decide a purchase.
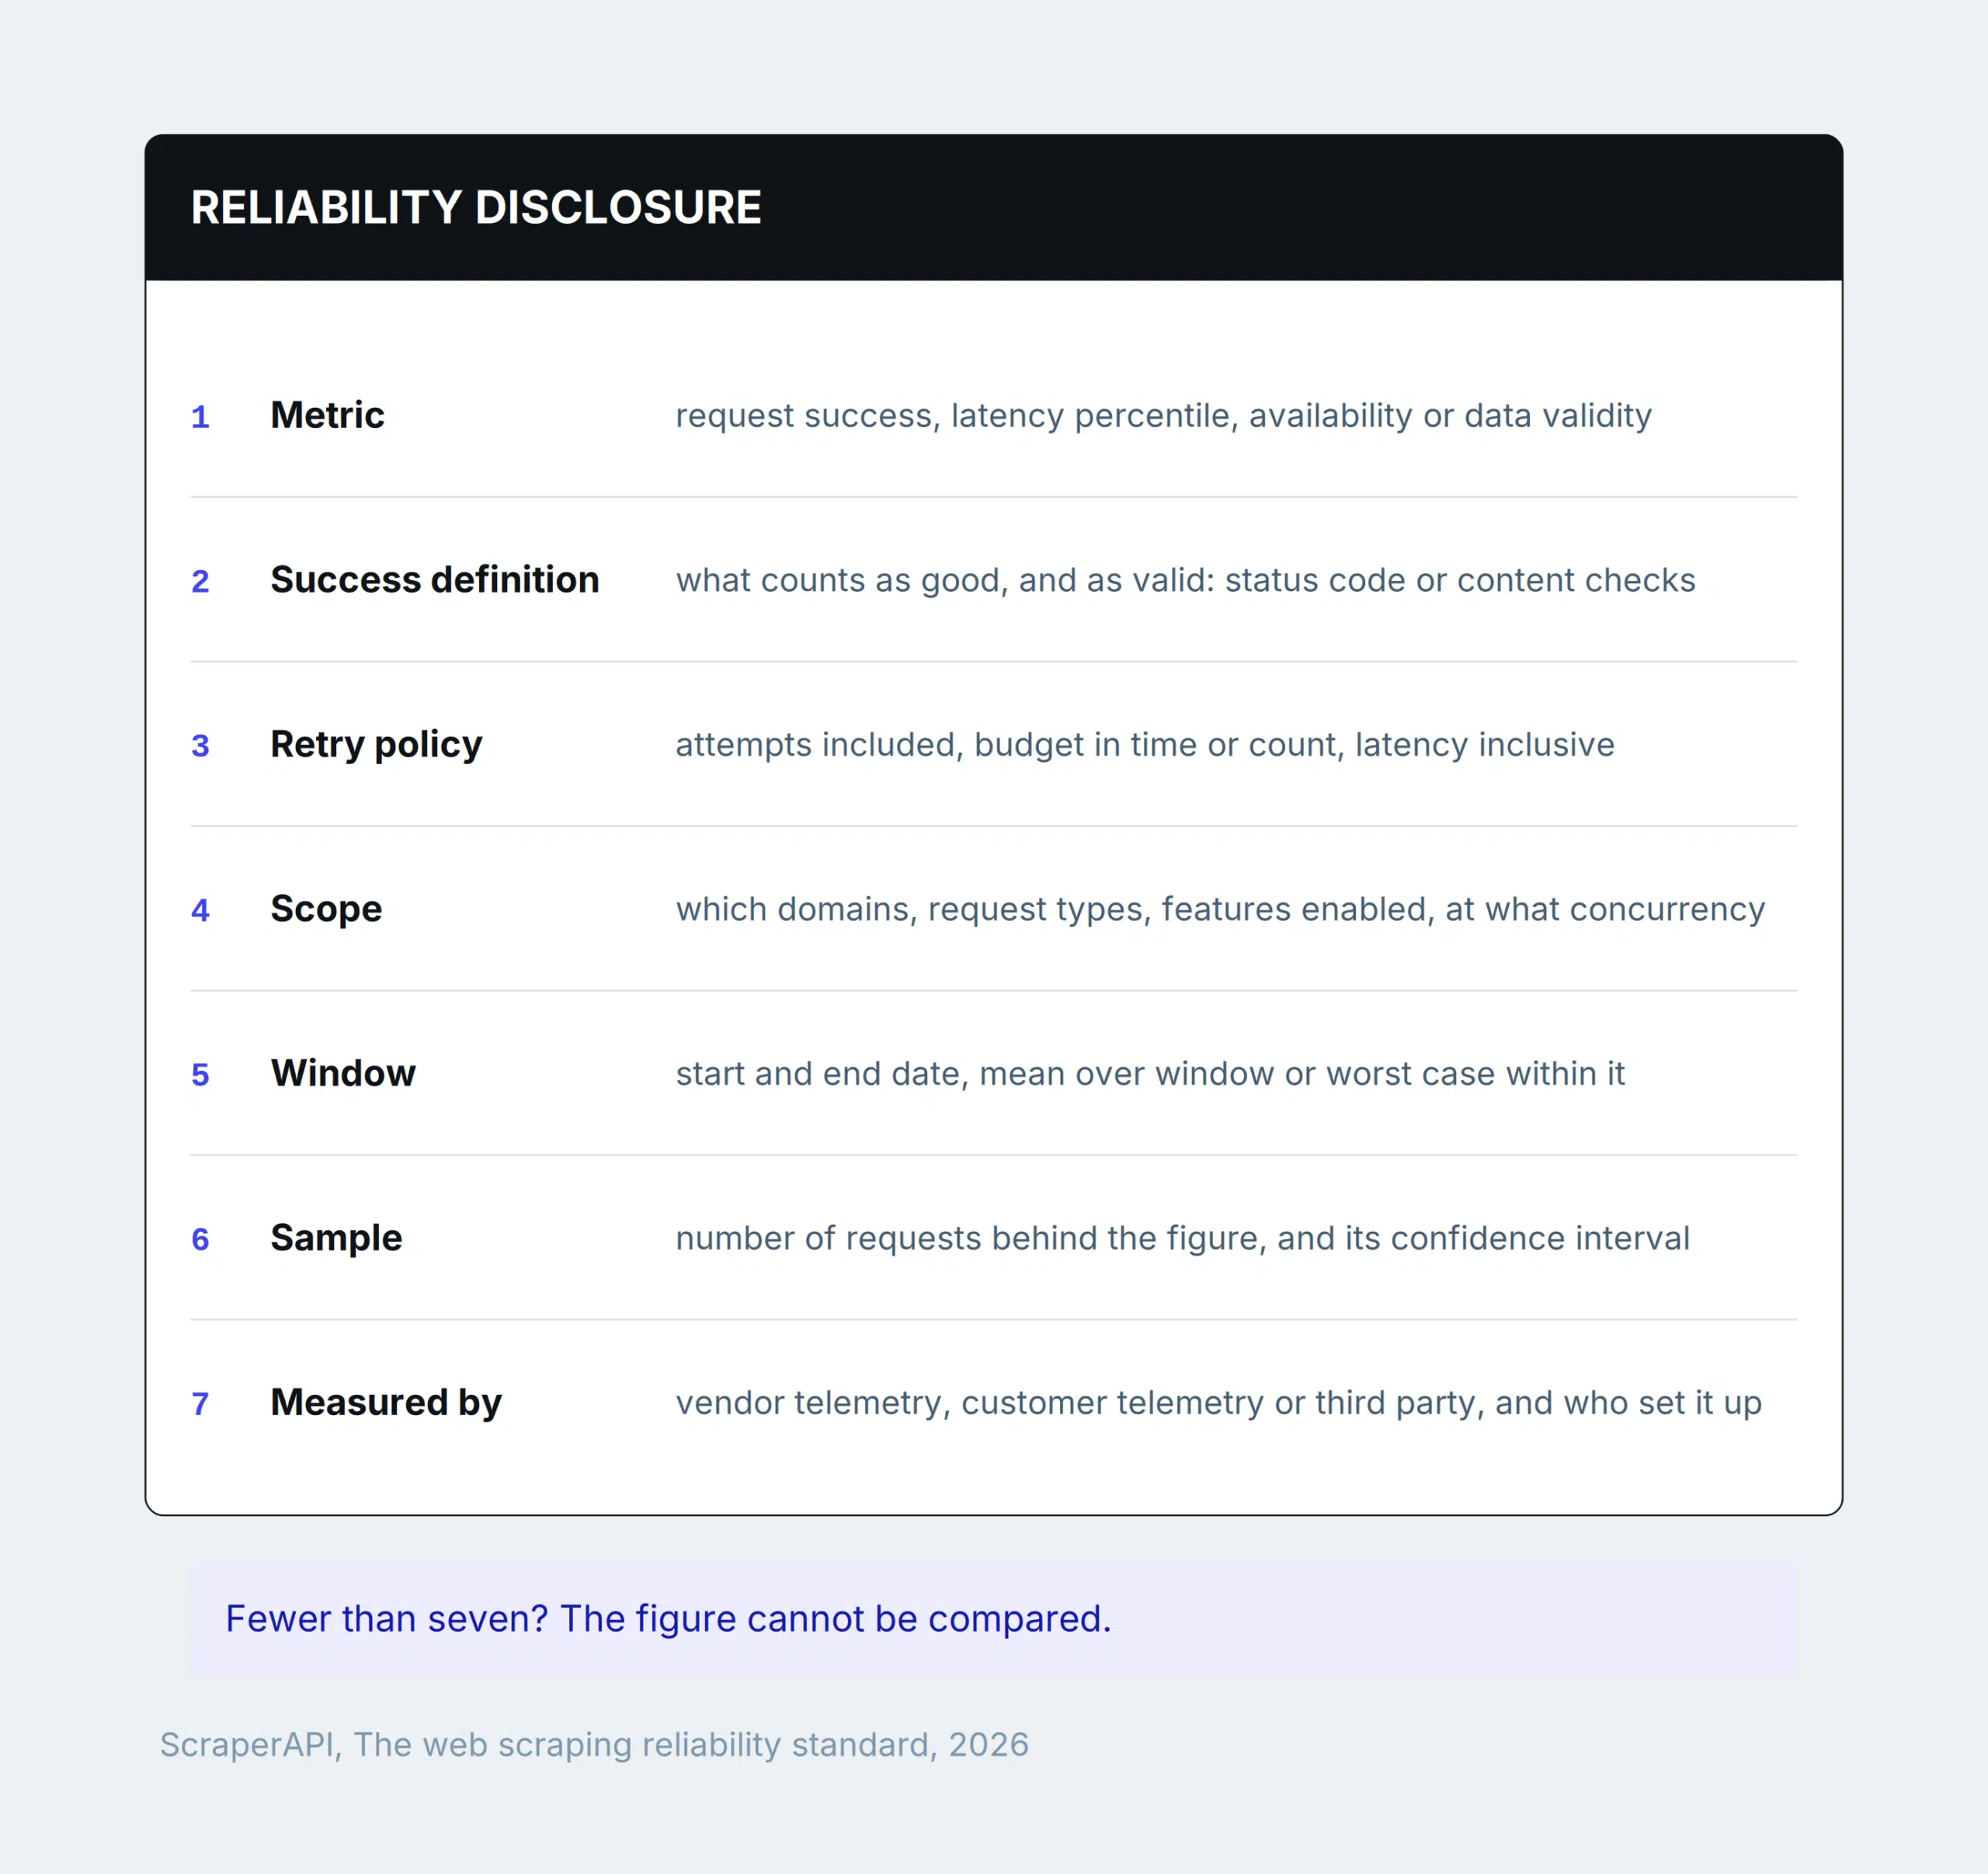
Figure 9. Print it out and hold vendor claims against it, ours included.
- Metric: Request success, latency percentile, availability, data validity.
- Success definition: What counts as good and what counts as valid. Status code only, or content checks, and which ones.
- Retry policy: Attempts included, budget in time or count, and whether the latency figure includes them.
- Scope: Which domains, which request types, which features enabled (rendering, premium routing, geotargeting), at what concurrency.
- Window: Start and end dates, and whether the number is a mean over the window or the worst case inside it.
- Sample: How many requests, and the confidence interval.
- Who measured it: Vendor telemetry, customer telemetry, or a third party, and who configured the client.
That last one carries more weight than it looks. At least one independent benchmarking publisher states openly that it shares its methodology with vendors in advance, and that results may therefore reflect a vendor’s best configuration rather than its default.
That’s a well-run benchmark being honest about a real limitation. A benchmark that doesn’t tell you how the clients were configured is unscoped, and should be read that way.
8. How to benchmark a web scraping API yourself
No published number, ours included, substitutes for measuring a provider against your own targets. Here’s a protocol that fits a two-week evaluation.
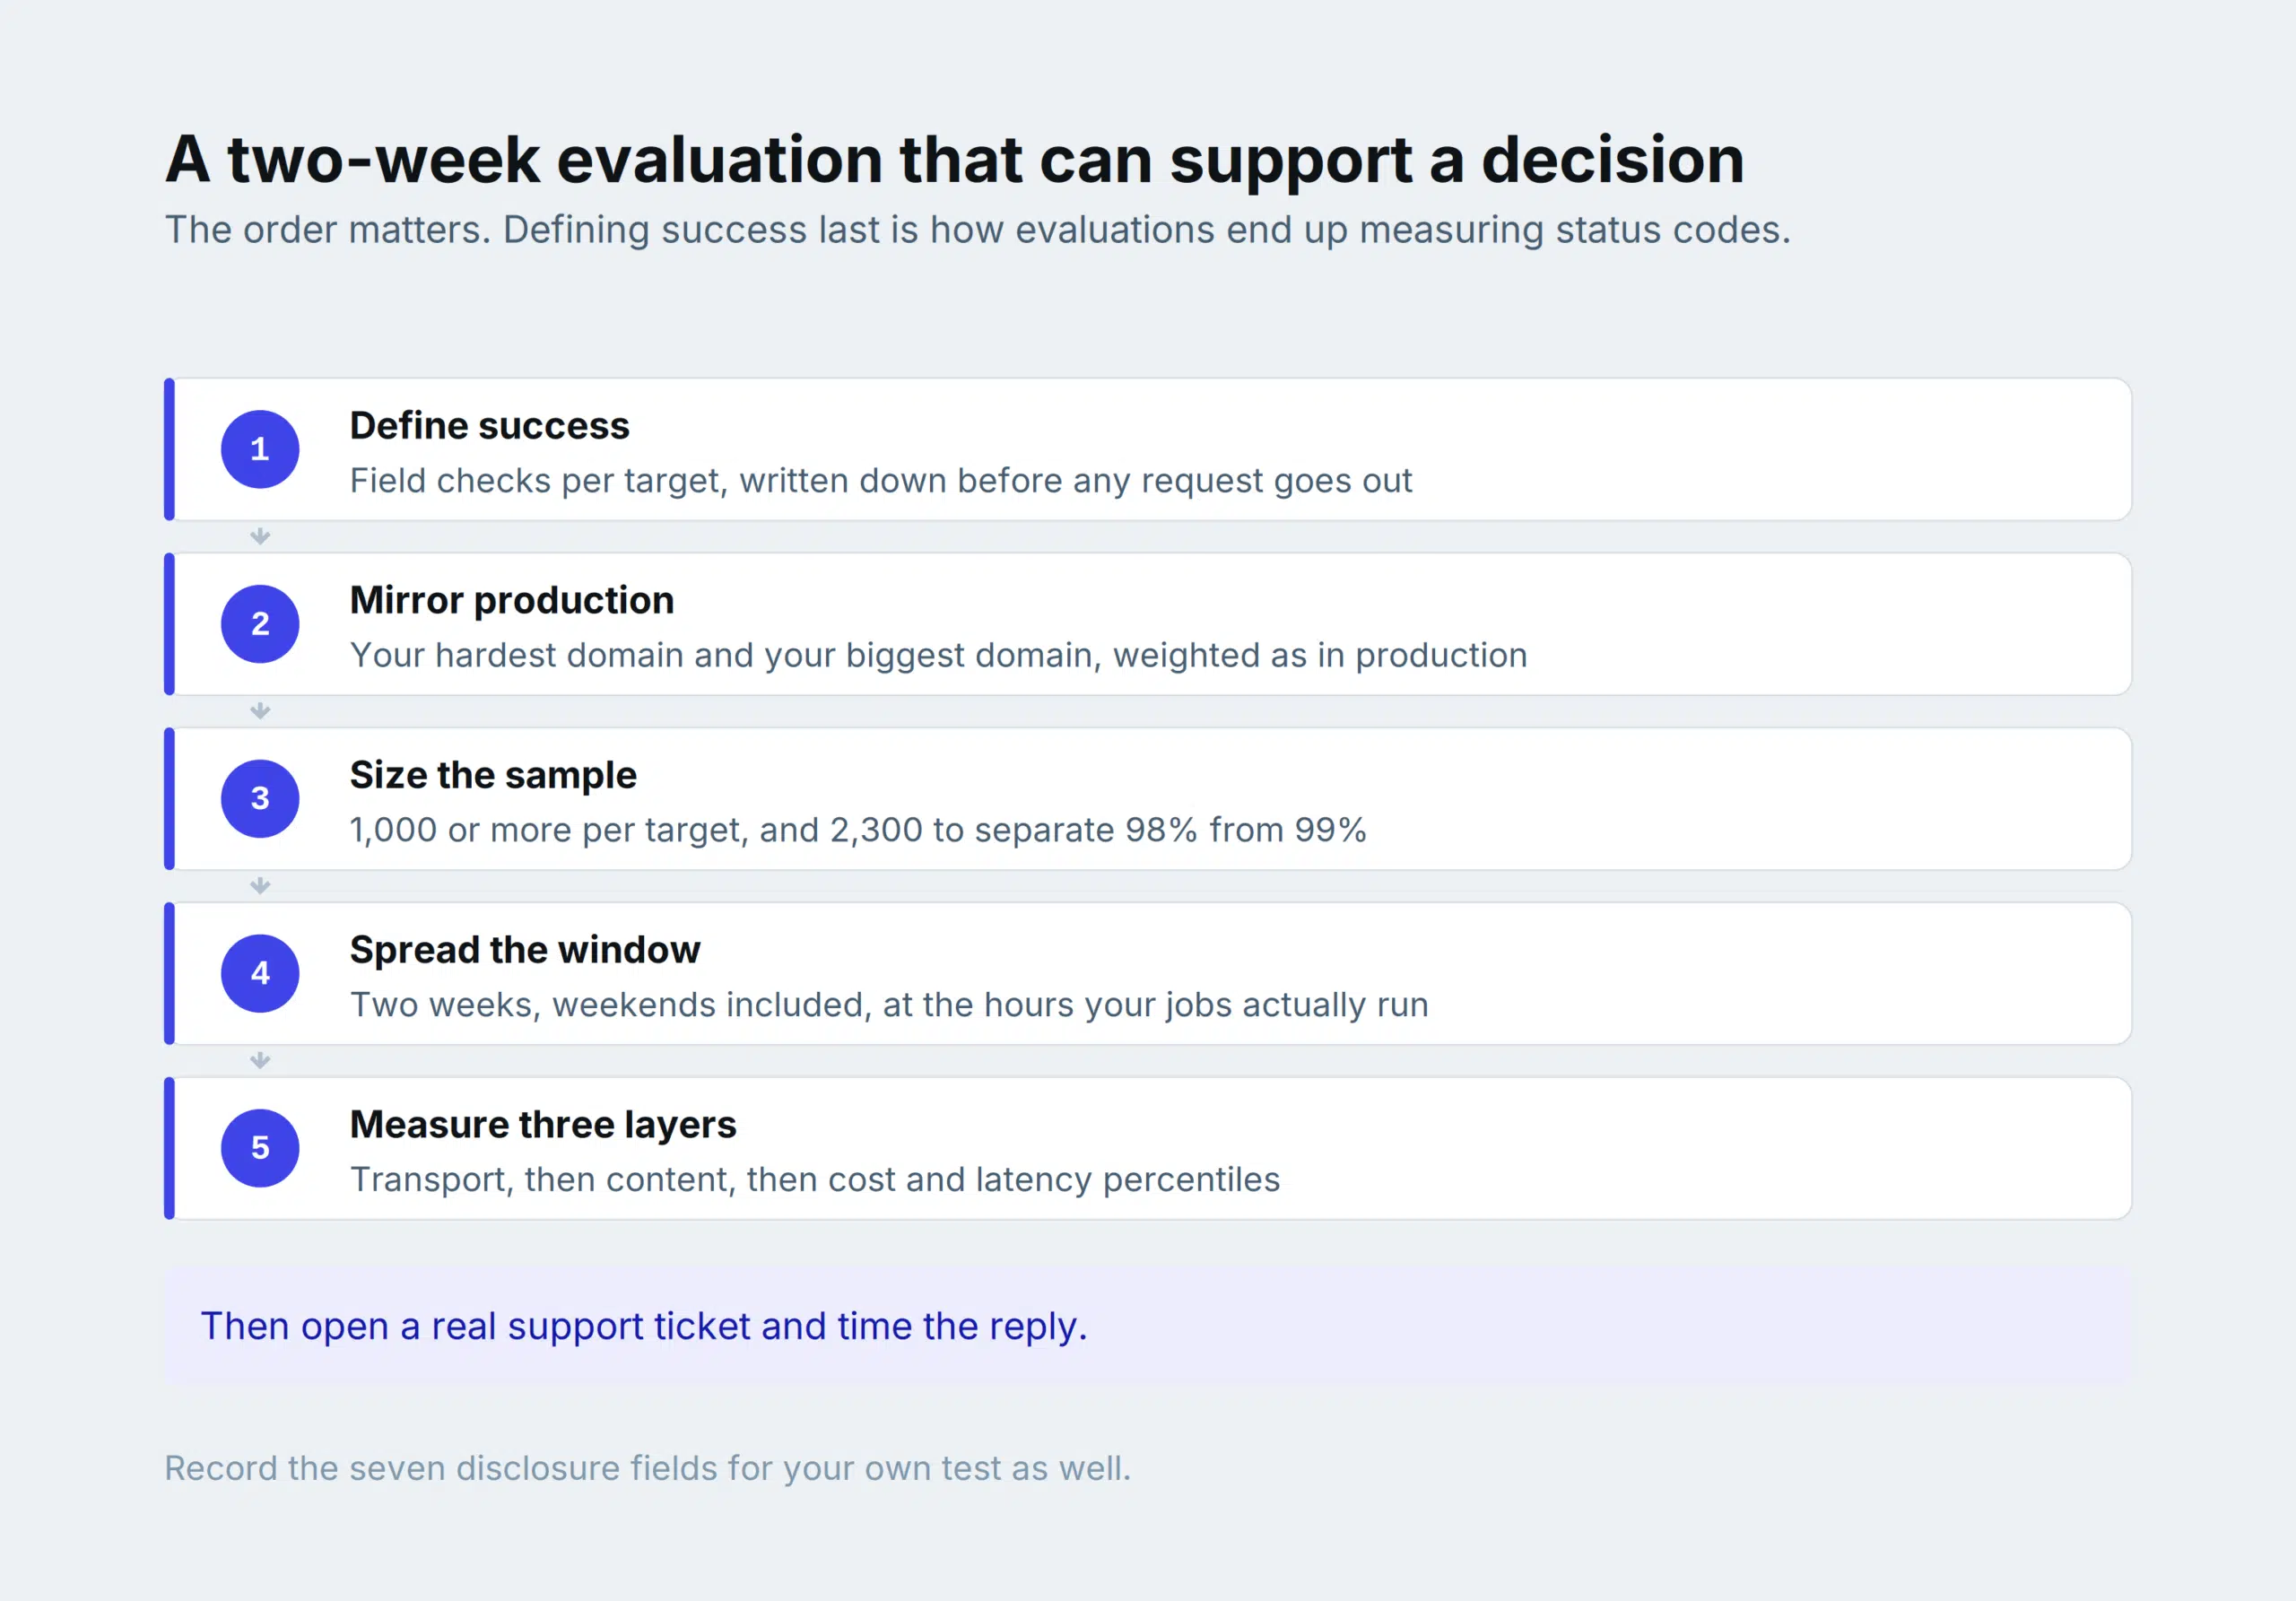
Figure 10. The order matters more than it looks.
- Write down what success means before you send a request: Per target, specify what makes a response usable: required fields, plausible value ranges, minimum page size, expected title pattern. Turn it into a check. Teams that skip this step end up measuring status codes by default, which is how you buy a provider that returns beautiful CAPTCHA pages.
- Build a target basket that looks like production: Your hardest domain, your highest-volume domain, and at least one you expect to be easy. Weight request counts to mirror your real mix. If 30% of production traffic hits one protected retailer, make it 30% of the test.
- Size the sample so the answer can support a decision: At least 1,000 requests per provider per target to see differences of a few points. Around 2,300 to separate 98% from 99%. If your budget only stretches to a few hundred, that’s fine, but be clear that the test can rule out a bad provider and cannot rank two good ones.
- Spread the window, and include your real hours: At least two weeks, weekdays and weekends, covering the times your production jobs actually run. Anti-bot behaviour varies by time of day and day of week. A test run entirely at 3 am against a US retailer isn’t a test of your workload.
- Instrument three layers, not one: Transport, meaning status codes and error classes. Content, meaning the checks from step 1. Cost and time, meaning credits per successful record, retry counts, and p50, p95, and p99.
- Log per attempt as well as per URL: Report first-attempt success, eventual success, and attempts per successful URL. The gap between the first two is a cost you’ll keep paying for as long as you’re a customer.
- Test at production concurrency: Success rates degrade under load, by different amounts for different providers, which is exactly why serious benchmarks publish results at several concurrency levels. A single-threaded test tells you nothing about fifty.
- Test the failure path deliberately: Request something blocked or non-existent. Do you get a clear, classified error, or a 200 with an empty body? Silent failures are the expensive kind, and how a provider behaves when it can’t deliver is as much a part of the product as how it behaves when it can.
- Time a support ticket, not just an outage: Open a real one during the trial and measure the reply time. For most production teams, the difference between vendors isn’t incident frequency; it’s what happens in the hour after an incident starts.
- Record your own methodology alongside your own result: Fill in the seven fields from section 7 for your test. In six months, when the number has moved, you’ll want to know whether the service changed or your test did.
Our web scraping best practices guide covers the client-side habits that keep a test honest, and there’s more on the operational side in five tips for building large-scale scrapers.
If you’re still deciding whether to run this test against providers at all, or to keep building in-house, proxy management in-house versus off-the-shelf and when to use proxies versus a scraping API are the honest versions of that comparison.
9. Fifteen reliability questions to ask a web scraping provider
Bring these to a vendor call. A provider who can answer them is a provider whose numbers you can use.
About the number:
- Does your published success rate measure attempts, URLs, or jobs?
- Does it count HTTP 200s or validate content? Which checks?
- Before or after retries, and what’s the retry budget?
- Which domains are in the denominator, and can you show me the per-domain breakdown for mine?
- What window, how many requests, and what’s the confidence interval?
- Is it your telemetry or an independent measurement?
About latency:
- What are p50, p95, and p99 for my target domains, and does that include failed attempts?
- What client timeout do you recommend, and what does that imply about your worst case?
About availability and accountability:
- Is your uptime figure about your API or about data access from target sites? Which one is contractually committed?
- What’s the remedy when you miss the objective, and has it ever actually been paid?
- Is your status page driven by automated health checks or updated by a human after someone complains?
- Do I pay for failed requests?
About data quality:
- What field-level monitoring do you run, and will you show me its output for my domains?
- When a target changes its layout and your parser breaks, how do I find out: your alert, or my dashboard?
- What’s your median time to restore a broken parser or a newly blocked domain?
Question 15 is the one experienced buyers care about most, and it’s the one least likely to appear on a website. Incidents get forgiven. Silence doesn’t.
If you’re building the business case internally, enterprise-scale data acquisition is the page most of our own customers forward to their procurement teams, and our pricing page has the credit mechanics you’ll need for a cost-per-record calculation.
10. How ScraperAPI reports reliability
Holding ourselves to the standard above has three consequences. One of them is uncomfortable, so we’ll start there.
10.1 What we’re retiring
We publish unscoped success-rate claims in several places, and they fail our own test.
A “99.9% uptime guarantee” sits on our pricing page. Some of our sales material has used “up to 99.999% uptime”. Several of our anti-bot pages carry a 99.99% success rate in the page title, on exactly the hardest protection systems in the market: Cloudflare, DataDome, Akamai, PerimeterX and Amazon WAF. Others promise “near-perfect success rates from the first request”.
None of those figures carries a definition, a window, a sample, or a retry disclosure. The “up to” construction is the worst of them, because it converts a claim into something unfalsifiable. And 99.999% availability permits 26 seconds of downtime a month, which is not a commitment any provider dependent on third-party websites should make in passing.
So: we’re removing “up to” framing from availability claims, and replacing unscoped cross-domain success rates with per-domain reporting. Where a number stays, it will carry the seven fields.
We’d rather publish a smaller figure we can define than a larger one we can’t.
10.2 What we already publish, and where to check it
These are documented mechanics rather than percentages, which makes them verifiable.
- We retry internally, and the retry window is part of the product: Our API retries a failing request for up to 70 seconds before returning an error. Any success rate you observe on our service is a post-retry figure by construction, and now you know it.
- We tell you to set a 70-second client timeout: That’s a disclosure about our tail latency, not a footnote. Our p99 on a hard target is measured in tens of seconds and your architecture should assume it.
- You aren’t billed for failures: A request that fails after the retry window returns an error and consumes no credits. Our billing is aligned with the metric, so when we fail, we don’t get paid. As accountability mechanisms go that one is harder to redefine in a marketing review than a percentage is.
- Our docs state an expected failure range: We publish that a low single-digit percentage of requests will fail, and that sustained failure rates above 10% mean something is wrong and you should escalate rather than absorb it.
- You can audit us per domain: The domain report shows, per domain and per date, which parameters were used, credits consumed, and the count of cancelled and failed requests. The /account endpoint exposes usage programmatically. You don’t have to accept our aggregate, because you can compute your own.
All of it lives in our documentation. A reliability claim you can check in the docs is worth more than one you can only read on a landing page.
10.3 One definitional edge we won’t bury
Our billing counts HTTP 200 and 404 as successful requests. A 404 means our infrastructure reached the target and the target said the page doesn’t exist. Depending on what you were doing, that’s either a useful answer or a wasted credit: fine if you’re validating a URL list, annoying if you expected a product page.
We’d rather you read it here than find it in an invoice.
11. Web scraping reliability terms, defined
Not all of these carry equal weight, so they are grouped by how much attention each deserves.
The three that matter
Practitioners who buy web data at scale tend to care about three things, and everything else in this list is a way of looking more closely at one of them.
- Success rate: Valid responses divided by attempted requests, over a stated window, for a stated target set, under a stated retry policy. Not meaningful without all four qualifiers. Where the retry policy allows more than one attempt, this is the combined figure: the chance that a request eventually succeeds, not that it succeeds the first time.
- Latency percentile (p50, p95, p99): The response time a given share of requests comes in under. p99 is the value your timeout has to survive. Percentiles cannot be averaged together.
- Data validity: Share of successful responses containing complete, correct, current data, verified by field-level checks.
Qualifiers, not extra metrics
These describe the three above rather than competing with them, and it helps to know which one each is really about.
- First-attempt success rate: Share of requests returning valid data with no retry. Presented as a reliability figure, it is really a latency and cost figure: the gap between it and the combined success rate is the retrying you are paying for.
- Retry budget: How many attempts, or how much time, a provider spends before declaring failure. The hidden variable in nearly every published success rate, and the dial that trades latency against success. Raise it and success goes up while response times get worse.
- Job completion rate: The chance that every request in a multi-request job succeeded. It compounds from per-request success rather than being independent of it, so a good success rate produces a good job completion rate by construction. It is worth calculating rather than asking for, because compounding makes a number that sounds fine at the request level look very different across a hundred URLs.
Terms to handle with care
These are borrowed from software reliability engineering, where the service being described is one the provider actually controls. Web data collection is not that, so read them as vocabulary for interpreting claims rather than as commitments a provider should be making.
- Availability (uptime): Share of a window in which the provider’s own service accepted and answered requests. A property of the provider, not of data access from target sites. Always establish which of the two a quoted figure covers.
- SLI, SLO, SLA: Indicator, objective, and objective-plus-consequence. A commitment with no consequence attached is an objective wearing a suit. Applied to data access rather than to a provider’s own API, an objective here is a promise to keep outperforming the engineering teams of the largest technology companies in the world, which is not a promise anyone in this category can keep.
- Error budget: The failure an objective permits. 99.9% availability is a budget of about 43 minutes a month. Useful for reasoning about a provider’s own infrastructure. Not meaningful for data access, for the reason above.
12. Methodology and sources
What we did:
We read the public reliability claims on the documentation, marketing pages, and partner listings of the leading web data providers, alongside the published methodologies and results of the independent benchmarking publishers active in this category, during 2026. We deliberately did not run our own competitive benchmark. A vendor-run comparison of rivals would be open to every methodological criticism this guide makes, plus the obvious one about self-interest. Where we cite a benchmark, we use the publisher’s own figures and note their stated method.
Statistical figures:
Confidence intervals are Wilson score intervals at 95%. Sample-size requirements are two-proportion tests at 95% confidence and 80% power. Availability-to-downtime conversions assume a 30-day month. The compounding and retry tables assume independence between attempts, which is a simplification worth naming: repeated attempts against the same target are positively correlated, so real retry gains are somewhat smaller than Figure 3 implies, and real job success is somewhat better than Figure 8 predicts.
Sources:
Reliability engineering framework:
- Google, Site Reliability Engineering, service level objectives.
- Google, The Site Reliability Workbook, implementing SLOs.
- Proxyway, how we test and review proxy services.
- Proxyway, Proxy Market Research 2026.
- Scrapeway, bi-weekly scraping API benchmarks.
- AIMultiple, web unblocker benchmarks.
- Our own documentation, for everything in section 10.2:
- API status codes, retry window, and billing of failed requests.
- General FAQ, expected failure rates.
- Credit usage and the domain report.
- Provider claims summarised in section 2 were read from those providers’ own public documentation, marketing pages and partner listings, and from the benchmarks above.
Frequently asked questions
What is a good success rate for web scraping?
There’s no single answer, because success rate belongs to the provider and target together. On unprotected pages, expect the high nineties from anyone competent. On heavily protected commercial targets, independent 2026 benchmarks put leading providers anywhere from roughly 62% to 97% depending on the target basket. Judge a provider on your domains rather than on a category average.
Why do web scraping providers publish such different success rates?
Because they’re measuring different things: status codes versus validated content, before versus after retries, easy versus hard target baskets, small versus large samples, and different windows. Any one of those can move a figure more than 20 points without the underlying service changing at all.
Is a 99.9% success rate claim realistic?
As a post-retry figure on unprotected targets, yes. As a first-attempt figure across heavily protected commercial sites, no, and independent benchmarking in 2026 doesn’t support it for anyone. The useful follow-up question is which of the two is being claimed.
What’s the difference between uptime and success rate in web scraping?
Uptime measures the provider’s own API availability. Success rate measures whether requests to third-party websites come back with usable data. A provider can be fully available and still fail because target sites decide the outcome. Only one of the two is inside the provider’s control, which is why an availability guarantee that covers data access should not be taken at face value from anyone.
How many requests do I need to test a scraping provider properly?
At least 1,000 per provider per target for a decision at the few-point level, and roughly 2,300 if you need to separate 98% from 99% with statistical confidence. A 100-request trial has a confidence interval wide enough to contain both a 93% and a 99% provider.
Should I include retries in my success rate?
Report both, and label them. Eventual success rate tells you whether you will get your data at all. First-attempt success rate tells you what that data costs in latency and credits, because every retry is another request the provider has to make. The gap between the two numbers is the best available predictor of your bill, and a provider quoting only the higher one is hiding the cheaper question.
Why does my success rate drop when I increase concurrency?
Two things happen at once. Target sites rate-limit and challenge more aggressively when they see sustained volume from correlated sources, and the provider’s own infrastructure starts queueing. Independent benchmarks report success at several concurrency levels for exactly this reason, and providers separate most at the top end. A result measured on one thread tells you nothing about fifty, so test at your production concurrency.
What is silent data degradation?
A response that passes transport checks and contains incomplete, stale or wrong data. It’s the most damaging reliability failure because nothing alerts on it, and it usually surfaces in your product before it surfaces in your monitoring. Field-level validation is the only real defence.

